Comparative Interactomics on the rise
I am sorry for the buzzwords but I just wanted to make the point of the exaggerated trend. Following the post on Notes from the Biomass I picked up the paper from Gandhi et al in Nature Genetics. The authors analyzed the human interactome from the Human Protein Reference Database, comparing it to other protein interaction networks from different species. Honestly I was a bit surprised to see so few new ideas on the paper and I agree with the post in Notes that they should have cited some previous works. For example the paper by Cesareni et al in FEBS Letters includes a similar analysis between S. cerevisiae and D. melanogaster. Also the people working on PathBlast have shown that maybe it is more informative to look for conserved sub-networks instead of the overlap between binary-interactions. I am personally very interested in network evolution and I was hoping the authors would elaborate a bit more on the subject. As usual they just dismiss the small overlap to low coverage. Is it so obvious that species that diverged 900My to 1By ago should have such similar networks ?
Like it was the case with comparative genomics, the ability to compare cellular interaction networks of different species should be far more informative than looking at individual maps. Unfortunately it is still not so easy to map a cellular interaction network has it is to get a genome.
Just out of curiosity, I think the first time the buzz words "comparative interactomics" were used in a journal was in a news and views by Uetz and Pankratz in 2004. Since then I think two papers picked up on the term, as you can see in this pubmed search (might change with time).
Monday, March 06, 2006
Marketing and science
I just spent 48 minutes seeing this video where Seth Godin spoke to Google about marketing. He talks a lot about how it is important to put out products that have a story, that compels people to go and tell their friends. This type of networking marketing is usually referred to as viral marketing (related to memetics). It is a really nice talk (he knows how to sell his ideas :) and it got me thinking of marketing in science.
The number of journals and publications keep growing at a fast pace. Out of curiosity I took from pubmed the number of publications published every year for the past decade and we can clearly see that the trend for the near future is, if anything, for further acceleration in the rate of publication.
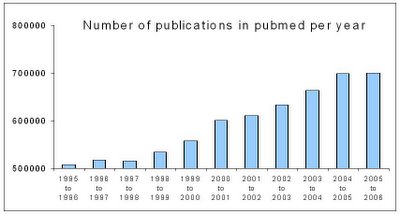
The other important point is that internet is probably changing the impact that an individual paper might have, irrespective of where it is published. It is easier with internet, for word-of-mouth (meaning emails, blogs, forums,etc) to raise awareness to good or controversial work than before.
So what I am getting at is that, on one hand the internet will likely help individual publications to get their deserved attention but on the other hand it will increase the importance of marketing in science. Before, to have attention, your work needed to be published in journals that were available in the libraries, now and I suspect, increasingly so in the future, you will have to have people talking about your work so that it raises above the thousands of publications published every year. It is too soon to say for sure what I prefer.
I just spent 48 minutes seeing this video where Seth Godin spoke to Google about marketing. He talks a lot about how it is important to put out products that have a story, that compels people to go and tell their friends. This type of networking marketing is usually referred to as viral marketing (related to memetics). It is a really nice talk (he knows how to sell his ideas :) and it got me thinking of marketing in science.
The number of journals and publications keep growing at a fast pace. Out of curiosity I took from pubmed the number of publications published every year for the past decade and we can clearly see that the trend for the near future is, if anything, for further acceleration in the rate of publication.
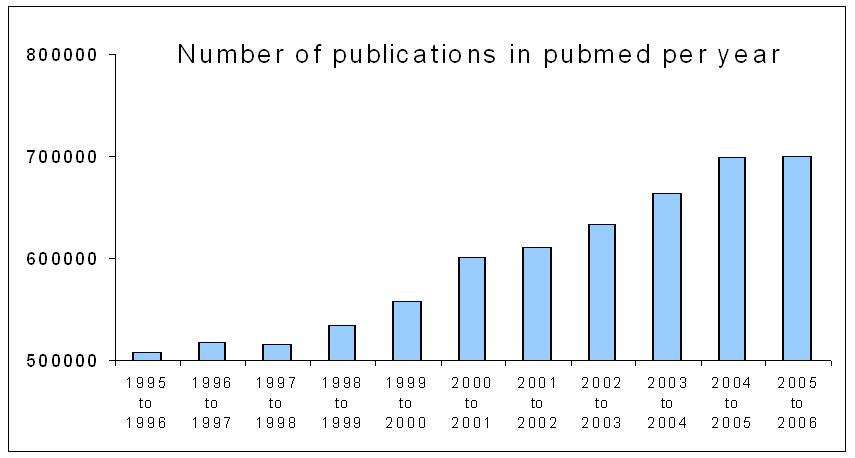
The other important point is that internet is probably changing the impact that an individual paper might have, irrespective of where it is published. It is easier with internet, for word-of-mouth (meaning emails, blogs, forums,etc) to raise awareness to good or controversial work than before.
So what I am getting at is that, on one hand the internet will likely help individual publications to get their deserved attention but on the other hand it will increase the importance of marketing in science. Before, to have attention, your work needed to be published in journals that were available in the libraries, now and I suspect, increasingly so in the future, you will have to have people talking about your work so that it raises above the thousands of publications published every year. It is too soon to say for sure what I prefer.
Tuesday, February 28, 2006
Track your comments with coComment
I am finally giving the coComment service a try and I will be experimenting with it for a while here on the blog. coComment aims to help us track the conversations we have on other blogs by aggregating comments and checking for replies. You decide to track or not a comment before submitting it and the comments tracked appear on your homepage at coComments. Alternatively you can read them via RSS feed or with a coComment box on your own blog. You can customize a lot the box so you could do a much better job than I did in trying to integrate it into your blog :).
You can find a lot more about this in these two posts on TechCrunch
Wednesday, February 15, 2006
Postgenomic
I have been wishing someone would come up with a science.memeorandum for some time and now there is one: Postgenomic. The site created by Stew (still in beta) aims to aggregate discussions going on in the life science blogs about papers, conferences and general science news. This adds a needed feedback to the science blogosphere and therefore will, in my opinion, increase the quality of discussion.
This site can for example become an excellent repository for comments on papers. Instead of adding a comment on a paper in the journal website now you can just blog about it and the content gets aggregated on postgenomic. I am not sure but I think we could make a greasemonkey script to check the current web page for a DOI and see if there are reviews about it in postgenomic and add a little link somewhere.
Some more links about it:
Nodalpoint
Notes and more Notes
I have been wishing someone would come up with a science.memeorandum for some time and now there is one: Postgenomic. The site created by Stew (still in beta) aims to aggregate discussions going on in the life science blogs about papers, conferences and general science news. This adds a needed feedback to the science blogosphere and therefore will, in my opinion, increase the quality of discussion.
This site can for example become an excellent repository for comments on papers. Instead of adding a comment on a paper in the journal website now you can just blog about it and the content gets aggregated on postgenomic. I am not sure but I think we could make a greasemonkey script to check the current web page for a DOI and see if there are reviews about it in postgenomic and add a little link somewhere.
Some more links about it:
Nodalpoint
Notes and more Notes
Tuesday, February 14, 2006
The search wars turn ugly
What will convince you to change your search engine ? So far it as been all about who gives the best results and who indexes the biggest number of pages. It looks like number two (Yahoo!) and number three (MSN) search engines are considering paying you to switch. How does MSNSearchAndWin sound like ? I also taught it was some kind of joke but you can try it yourself.
To be fair, someone mentioned also that Google is thinking of paying Dell to have Google software pre-installed on the new computers.
I would prefer it was about new innovation and not just about how as more cash to give to the users. It even sounds a bit ridiculou. It is not only free they are thinking of paying us to use it. Very competitive market.
What will convince you to change your search engine ? So far it as been all about who gives the best results and who indexes the biggest number of pages. It looks like number two (Yahoo!) and number three (MSN) search engines are considering paying you to switch. How does MSNSearchAndWin sound like ? I also taught it was some kind of joke but you can try it yourself.
To be fair, someone mentioned also that Google is thinking of paying Dell to have Google software pre-installed on the new computers.
I would prefer it was about new innovation and not just about how as more cash to give to the users. It even sounds a bit ridiculou. It is not only free they are thinking of paying us to use it. Very competitive market.
Monday, February 13, 2006
BIND in the news
There is another editorial in the last issue of Nature Biotech about database funding. It focuses on BIND, explaining the growth and later decline (due to lack of funding) of this well known interaction database. Last December, BIND and other Blueprint Initiative intellectual property was bought by Unleashed Informatics but as far as I can understand, this deal merely keeps the database available on the site and there will be no further updating for now. Knowing that both BIND and unleashed were created within the Blueprint Initiative led by principal investigator Christopher Hogue (also Chief Scientific Officer of Unleashed Informatics) then this deal was probably just symbolic and a way to increase the value of the company.
According to the Nature Biotech article BIND used up "$17.3 million in federal and Ontario government funding and another $7.8 million from the private sector" to create it's value. Without the details it looks strange that so much value, mostly built with public money, ends up in a private company. Unleashed had to agreed to maintain the access to the existing value free for all and I guess it will use BIND to attract possible buyers to their tools.
Christopher Hogue posted a pessimistic comment here sometime ago about the future of databases in general. This editorial in Nature Biotech argues that it would take two important steps to allow for more permanent databases. The first step would be for the major funding agencies to accept and discuss the need for longer lived databases. The second step would be to create mechanism to decide what databases should be recognized as matured standards.
I thought that with examples like pubmed, the sequence databases and the PDB that the need for long lived databases was obvious by know to the funding bodies. The second step is a bit more tricky. Creating a minimal and stable standard for a type of data is a complicated process and it is not obvious when a database supports such a community of researchers that it would make sense to give it maintenance funding.
Some toughts from Neil, Spitshine
A similar discussion in Nodalpoint
There is another editorial in the last issue of Nature Biotech about database funding. It focuses on BIND, explaining the growth and later decline (due to lack of funding) of this well known interaction database. Last December, BIND and other Blueprint Initiative intellectual property was bought by Unleashed Informatics but as far as I can understand, this deal merely keeps the database available on the site and there will be no further updating for now. Knowing that both BIND and unleashed were created within the Blueprint Initiative led by principal investigator Christopher Hogue (also Chief Scientific Officer of Unleashed Informatics) then this deal was probably just symbolic and a way to increase the value of the company.
According to the Nature Biotech article BIND used up "$17.3 million in federal and Ontario government funding and another $7.8 million from the private sector" to create it's value. Without the details it looks strange that so much value, mostly built with public money, ends up in a private company. Unleashed had to agreed to maintain the access to the existing value free for all and I guess it will use BIND to attract possible buyers to their tools.
Christopher Hogue posted a pessimistic comment here sometime ago about the future of databases in general. This editorial in Nature Biotech argues that it would take two important steps to allow for more permanent databases. The first step would be for the major funding agencies to accept and discuss the need for longer lived databases. The second step would be to create mechanism to decide what databases should be recognized as matured standards.
I thought that with examples like pubmed, the sequence databases and the PDB that the need for long lived databases was obvious by know to the funding bodies. The second step is a bit more tricky. Creating a minimal and stable standard for a type of data is a complicated process and it is not obvious when a database supports such a community of researchers that it would make sense to give it maintenance funding.
Some toughts from Neil, Spitshine
A similar discussion in Nodalpoint
Monday, February 06, 2006
Become a fonero and change the world
Today I read about FON, a global community of people that share wi-fi access. They just made the news because they announced support from several well known companies (Google , Skype, Sequoia Capital, and Index Ventures) that will surely catapult FON into the sky. The basic idea is to turn any wifi router into a hotspot and have people share their internet connection by installing some software on their routers or buying pre-configured wireless routers from the company. You can only use other people's FON hotspots if you are paying for one ISP at home so this is also good for the internet service providers. You can try to make money with your FON hotspot (they call these users Bills) or you can be more utopian and give away your internet connection for free (and be called a Linus). If you do not have a FON account you are called an alien but you can still connect to a FON hotspot and you will have to pay just like at any hotspot (and the ISPs get some money from this as well).
At first glance it looks like an all win cenario but only time will tell. It is certainly one case where the more that join the better the service will become and if this gets of the ground then once you pay for a connection at home you have it almost everywhere.
This is one of those simple utopian ideas with enough practical sense to make an impact so I think I will give it a try :).
Today I read about FON, a global community of people that share wi-fi access. They just made the news because they announced support from several well known companies (Google , Skype, Sequoia Capital, and Index Ventures) that will surely catapult FON into the sky. The basic idea is to turn any wifi router into a hotspot and have people share their internet connection by installing some software on their routers or buying pre-configured wireless routers from the company. You can only use other people's FON hotspots if you are paying for one ISP at home so this is also good for the internet service providers. You can try to make money with your FON hotspot (they call these users Bills) or you can be more utopian and give away your internet connection for free (and be called a Linus). If you do not have a FON account you are called an alien but you can still connect to a FON hotspot and you will have to pay just like at any hotspot (and the ISPs get some money from this as well).
At first glance it looks like an all win cenario but only time will tell. It is certainly one case where the more that join the better the service will become and if this gets of the ground then once you pay for a connection at home you have it almost everywhere.
This is one of those simple utopian ideas with enough practical sense to make an impact so I think I will give it a try :).
Monday, January 30, 2006
Sunday, January 29, 2006
BioPerl has a new site
If you use BioPerl go have a look at the re-designed site. From the full announcement at OBF:
"I am pleased to announce the release of a new website for BioPerl. The site is based on the mediawiki software that was developed for the wikipedia project. We intend the site to be a place for community input on documentation and design for the BioPerl project. There is also a fair amount of documentation started surrounding bioinformatics tools and techniques applicable to using BioPerl and some of the authors who created these resources."
If you use BioPerl go have a look at the re-designed site. From the full announcement at OBF:
"I am pleased to announce the release of a new website for BioPerl. The site is based on the mediawiki software that was developed for the wikipedia project. We intend the site to be a place for community input on documentation and design for the BioPerl project. There is also a fair amount of documentation started surrounding bioinformatics tools and techniques applicable to using BioPerl and some of the authors who created these resources."
Friday, January 27, 2006
Meta bloguing
I changed a couple of things on the blog template. If anybody reads this with an aggregator and all previous posts appear as updated please let me know.
I added a new section on the right bar were I plan to keep some previous post that might be interesting to discuss. I had this change in mind after reading this post in Notes from the Biomass about blogging. It is true that blogging platforms don't make it easy to revisit ideas. I'll try to find other ways to do this.
I also updated the blogroll with some links. Neil's blog and Yakafokon on bioinformatics, some tech blogs I particularly like and a the blog of a portuguese friend of mine.
I changed a couple of things on the blog template. If anybody reads this with an aggregator and all previous posts appear as updated please let me know.
I added a new section on the right bar were I plan to keep some previous post that might be interesting to discuss. I had this change in mind after reading this post in Notes from the Biomass about blogging. It is true that blogging platforms don't make it easy to revisit ideas. I'll try to find other ways to do this.
I also updated the blogroll with some links. Neil's blog and Yakafokon on bioinformatics, some tech blogs I particularly like and a the blog of a portuguese friend of mine.
Our Collective Mind II
Some time ago I posted an unusual short text about collective intelligence. I think it was motivated by the web2.0 explosion, all the blogging, social websites and the layer of other services tracking these human activities in real time. The developments in the last 2-3 years were not so much a question of technical innovation since most of the tools were already developed but it was mostly a massification effect. A lot more people started to participate online instead of just browsing. This participation is very easy to track and we have automatic services that can, for example, tell us what people are currently talking about. One can think of these services as a form of self awareness. If you go to tech.memeorandum you can see a computer algorithm tracking the currently most talked about subjects in technology and organizing them into conversations. This does not mean that the web can understand what is being talked about but it is self aware.
I read today a (very long) post by Nova Spinack about this subject of self awareness and how he proposes that we should build this on a large scale. Although I agree that this type of services are very useful I am not sure that one should try to purposely build some form of collective intelligence on such abstract terms. This idea of having everything collected under the same service feels to restrictive and not very functional. I would prefer a diversity and selection approach, just let the web decide. There is a big marked for web services right now and I don't see it fading any time soon. Therefore if collective intelligence is possible and useful then rapidly services will be built on top of each other to produce it.
If you have any interest on the topic and endorse his opinion write a post and trackback to him.
Some time ago I posted an unusual short text about collective intelligence. I think it was motivated by the web2.0 explosion, all the blogging, social websites and the layer of other services tracking these human activities in real time. The developments in the last 2-3 years were not so much a question of technical innovation since most of the tools were already developed but it was mostly a massification effect. A lot more people started to participate online instead of just browsing. This participation is very easy to track and we have automatic services that can, for example, tell us what people are currently talking about. One can think of these services as a form of self awareness. If you go to tech.memeorandum you can see a computer algorithm tracking the currently most talked about subjects in technology and organizing them into conversations. This does not mean that the web can understand what is being talked about but it is self aware.
I read today a (very long) post by Nova Spinack about this subject of self awareness and how he proposes that we should build this on a large scale. Although I agree that this type of services are very useful I am not sure that one should try to purposely build some form of collective intelligence on such abstract terms. This idea of having everything collected under the same service feels to restrictive and not very functional. I would prefer a diversity and selection approach, just let the web decide. There is a big marked for web services right now and I don't see it fading any time soon. Therefore if collective intelligence is possible and useful then rapidly services will be built on top of each other to produce it.
If you have any interest on the topic and endorse his opinion write a post and trackback to him.
Wednesday, January 18, 2006
Power law distributions
Almost every time a lot of hype is built around an idea there is general backlash against the very same idea. In technology this happens regularly and it is maybe due to a snowball effect that leads to abuse. Initially a new concept is proposed that leads to useful new products and this in turn increases interest and funding (venture capital, etc). In response, several people copy the concept or merely tag their work with the same buzz to attract interest. Soon enough everyone is doing the same thing and the new concept reaches world fame. At this point it is hard to find actual good products based on the initial idea among all the noise. For a recent tech example just think of the web2.0 meme. Every startup now a days releases their projects in beta with some sort of tagging/social/mash-up thing. The backlash in already happening for web2.0.
What about the title ?
I had already mentioned a review article about power-law distributions. The author voiced some concern over the exaggerated conclusions researchers are making about the observation of these distributions in complex networks. Is the backlash coming for this hype?
Recently Oliveira and Barabasi published yet another paper on the ubiquity of power laws. This time it was about the correspondence patterns Darwin and Einstein where they claim that the time delays for the replies follow a power-law. This work is similar to earlier work by Barabasi about email correspondence. Quickly after, a comment was published in Nature suggesting that the data is a better fit for the lognormal distribution and this generated some discussion on the web. There is also some claims of similar previous work using the same data not properly cited.
The best summary of the whole issue comes in my opinion from Michael Mitzenmacher:
"While the rebuttal suggests the data is a better fit for the lognormal distribution, I am not a big believer in the fit-the-data approach to distinguish these distributions. The Barabasi paper actually suggested a model, which is nice, (...) anyone can come up with a power law model. The challenge is figuring out how to show your model is actually right."
Other papers have recently put questions also on the quality of the data underlying some of these studies. Is life all log-normal after all :) ?
What I actually want to discuss is the hype. Going back to the beginning of the post, how can we keep science from generating such hype around particular memes. People like Barabasi are capable of captivating the imagination of a broad audience and help bring society closer to science but usually at some cost. I think this is tied to science funding. What gets funded is what is perceived as the cutting edge, the trendy subjects. Trendy things get a lot of funding and more visibility until the whole thing crashes down with the weight of all the noise in the field.
In a brilliant paper (the one about a radio :) Lazebnik remembers some advice from David Papermaster:
"David said that every field he witnessed during his decades in biological research developed quite similarly. At the first stage, a small number of scientists would somewhat leisurely discuss a problem that would appear esoteric to others (...) Then, an unexpected observation (...) makes many realize that the previously mysterious process can be dissected with available tools and, importantly, that this effort may result in a miracle drug. At once, the field is converted into a Klondike gold rush with all the characteristic dynamics, mentality, and morals. (...) The assumed proximity of this imaginary nugget easily attracts both financial and human resources, which results in a rapid expansion of the field. The understanding of the biological process increases accordingly and results in crystal clear models that often explain everything and point at targets for future miracle drugs.(...) At some point, David said, the field reaches a stage at which models, that seemed so complete, fall apart, predictions that were considered so obvious are found to be wrong, and attempts to develop wonder drugs largely fail. (...) In other words, the field hits the wall, even though the intensity of research remains unabated for a while, resulting in thousands of publications, many of which are contradictory or largely descriptive."
Is this necessary ? Is there something about the way science is made that leads to this ? Can we change it?
Almost every time a lot of hype is built around an idea there is general backlash against the very same idea. In technology this happens regularly and it is maybe due to a snowball effect that leads to abuse. Initially a new concept is proposed that leads to useful new products and this in turn increases interest and funding (venture capital, etc). In response, several people copy the concept or merely tag their work with the same buzz to attract interest. Soon enough everyone is doing the same thing and the new concept reaches world fame. At this point it is hard to find actual good products based on the initial idea among all the noise. For a recent tech example just think of the web2.0 meme. Every startup now a days releases their projects in beta with some sort of tagging/social/mash-up thing. The backlash in already happening for web2.0.
What about the title ?
I had already mentioned a review article about power-law distributions. The author voiced some concern over the exaggerated conclusions researchers are making about the observation of these distributions in complex networks. Is the backlash coming for this hype?
Recently Oliveira and Barabasi published yet another paper on the ubiquity of power laws. This time it was about the correspondence patterns Darwin and Einstein where they claim that the time delays for the replies follow a power-law. This work is similar to earlier work by Barabasi about email correspondence. Quickly after, a comment was published in Nature suggesting that the data is a better fit for the lognormal distribution and this generated some discussion on the web. There is also some claims of similar previous work using the same data not properly cited.
The best summary of the whole issue comes in my opinion from Michael Mitzenmacher:
"While the rebuttal suggests the data is a better fit for the lognormal distribution, I am not a big believer in the fit-the-data approach to distinguish these distributions. The Barabasi paper actually suggested a model, which is nice, (...) anyone can come up with a power law model. The challenge is figuring out how to show your model is actually right."
Other papers have recently put questions also on the quality of the data underlying some of these studies. Is life all log-normal after all :) ?
What I actually want to discuss is the hype. Going back to the beginning of the post, how can we keep science from generating such hype around particular memes. People like Barabasi are capable of captivating the imagination of a broad audience and help bring society closer to science but usually at some cost. I think this is tied to science funding. What gets funded is what is perceived as the cutting edge, the trendy subjects. Trendy things get a lot of funding and more visibility until the whole thing crashes down with the weight of all the noise in the field.
In a brilliant paper (the one about a radio :) Lazebnik remembers some advice from David Papermaster:
"David said that every field he witnessed during his decades in biological research developed quite similarly. At the first stage, a small number of scientists would somewhat leisurely discuss a problem that would appear esoteric to others (...) Then, an unexpected observation (...) makes many realize that the previously mysterious process can be dissected with available tools and, importantly, that this effort may result in a miracle drug. At once, the field is converted into a Klondike gold rush with all the characteristic dynamics, mentality, and morals. (...) The assumed proximity of this imaginary nugget easily attracts both financial and human resources, which results in a rapid expansion of the field. The understanding of the biological process increases accordingly and results in crystal clear models that often explain everything and point at targets for future miracle drugs.(...) At some point, David said, the field reaches a stage at which models, that seemed so complete, fall apart, predictions that were considered so obvious are found to be wrong, and attempts to develop wonder drugs largely fail. (...) In other words, the field hits the wall, even though the intensity of research remains unabated for a while, resulting in thousands of publications, many of which are contradictory or largely descriptive."
Is this necessary ? Is there something about the way science is made that leads to this ? Can we change it?
Thursday, January 12, 2006
European Research Council (ERC)
For those of you who don't usually read about European research policies, the European Research Council is a projected European structure being designed to support basic research. It is now clear that the ERC will be formed but it is still unknown how much money the EU budget will reserve for it. Recently the Scientific Council of the future ERC was nominated and the chairman is none other than Fotis Kafatos, the former EMBL director. Kafatos term as EMBL director ended in May last year and his nomination as chairman of the ERC will, in my opinion, strengthen the research council and hopefully help it attract the funding required.
For further reading:
Kafatos named Chairman of ERC Council (EMBL announcement)
Chairman explains Europe's research council (interview for Nature)
Election of Chairman of Scientific Council (press release hidden among several other)
For those of you who don't usually read about European research policies, the European Research Council is a projected European structure being designed to support basic research. It is now clear that the ERC will be formed but it is still unknown how much money the EU budget will reserve for it. Recently the Scientific Council of the future ERC was nominated and the chairman is none other than Fotis Kafatos, the former EMBL director. Kafatos term as EMBL director ended in May last year and his nomination as chairman of the ERC will, in my opinion, strengthen the research council and hopefully help it attract the funding required.
For further reading:
Kafatos named Chairman of ERC Council (EMBL announcement)
Chairman explains Europe's research council (interview for Nature)
Election of Chairman of Scientific Council (press release hidden among several other)
Saturday, December 10, 2005
Linking out (blogs@nature && workflows)
Rolf Apweiler called bloggers exhibitionist in a recent news special in Nature -"I have my doubts that blogging reduces information overload, but blogging will survive as it appeals to all the exhibitionists,". I hope this simplistic opinion is supported by more reasoning that was not included in the news piece because of lack of space. Blogging appeals to the easy creation of content, it makes it easier for people to have a voice. What gets people attention is how good (or bad) the content is, not the particular connections or any other bias. This makes blogs one the most democratic content medium I am aware of (compare it to newspapers, radio, tv). Discussion in Notes from the Biomass
Check out some interesting post on workflows in Hublog and Flags and Lollipops
Rolf Apweiler called bloggers exhibitionist in a recent news special in Nature -"I have my doubts that blogging reduces information overload, but blogging will survive as it appeals to all the exhibitionists,". I hope this simplistic opinion is supported by more reasoning that was not included in the news piece because of lack of space. Blogging appeals to the easy creation of content, it makes it easier for people to have a voice. What gets people attention is how good (or bad) the content is, not the particular connections or any other bias. This makes blogs one the most democratic content medium I am aware of (compare it to newspapers, radio, tv). Discussion in Notes from the Biomass
Check out some interesting post on workflows in Hublog and Flags and Lollipops
Back to roots
I like bioinformatics because it is so useful at pointing out the next useful experiments and helping to extract knowledge from your data. This is why I think it is possible and useful to do experimental work alongside with computational work.
I have spent the last week back in the bench doing some biochemistry. I usually don't do much bench work although I have a biochemistry degree. It is at the moment not easy to keep up doing my computational work while doing the lab work but I want, until the end of my PhD, to find a way to keep doing both things at the same time. I should divide my time between the two mind sets but I am not sure of the best way.
Any ideas ?
I like bioinformatics because it is so useful at pointing out the next useful experiments and helping to extract knowledge from your data. This is why I think it is possible and useful to do experimental work alongside with computational work.
I have spent the last week back in the bench doing some biochemistry. I usually don't do much bench work although I have a biochemistry degree. It is at the moment not easy to keep up doing my computational work while doing the lab work but I want, until the end of my PhD, to find a way to keep doing both things at the same time. I should divide my time between the two mind sets but I am not sure of the best way.
Any ideas ?
Wednesday, November 30, 2005
Firefox 1.5
A quick post to promote the release of a new version of firefox. If you already have it, go get it here. If you don't have it yet, give it a try, it takes one or two minutes to install and has nice advantages compared to some other popular browsers (just an example of the top of my head ... it is better than the internet explorer :) ).
There are going to be some potentially funny films to see in Spreadfirefox.com.
I am still playing around with but the first surprise is immediate, much quicker to move between tabs. You can now move the tabs around with drag and drop to re-order them. New features listed here.

A quick post to promote the release of a new version of firefox. If you already have it, go get it here. If you don't have it yet, give it a try, it takes one or two minutes to install and has nice advantages compared to some other popular browsers (just an example of the top of my head ... it is better than the internet explorer :) ).
There are going to be some potentially funny films to see in Spreadfirefox.com.
I am still playing around with but the first surprise is immediate, much quicker to move between tabs. You can now move the tabs around with drag and drop to re-order them. New features listed here.

Monday, November 28, 2005
Meta Blogging
If by any strange reason you are searching for some blogs to read allow me to make a suggestion. Via NyTimes I found this site called TravelBlog for people blogging while traveling. From the site :"Travel Blog is a collection of travel journals, diaries, stories and photos from all around the world, ordinary people doing extraordinary things. For travellers, this site includes lots of features that help keep family and friends back home up to date with your adventure."
I would not put any of these in my usual reads but maybe I will check back to this page before my next long holidays ... umm .. sometime after I finish my phd.
If by any strange reason you are searching for some blogs to read allow me to make a suggestion. Via NyTimes I found this site called TravelBlog for people blogging while traveling. From the site :"Travel Blog is a collection of travel journals, diaries, stories and photos from all around the world, ordinary people doing extraordinary things. For travellers, this site includes lots of features that help keep family and friends back home up to date with your adventure."
I would not put any of these in my usual reads but maybe I will check back to this page before my next long holidays ... umm .. sometime after I finish my phd.
Sunday, November 27, 2005
SyntheticBiology@Nature.com
This week Nature has a special issue on <buzz>Synthetic Biology</buzz>. I have currently a kind of love/hate relationship with trends in biology. It is easy to track the trends (in the recent past: genomics, proteomics, bioinformatics, systems biology, nanotechnology, synthetic biology) and it is somehow fascinating to follow them and watch them propagate. It holds for me a similar fascination has seeing a meme propagate in the web. Someone will still write a thesis on how a kid was able to put up a webpage like this one and make truck load of money selling pixels just because he ignited the curiosity of people on a global scale.
There is always a reason behind each rising trend in biology, but they are clearly too short lived to deliver on their expectations, so what is the point ? Why do these waves of buzz exist in research ? The mentality of engineering in biology is not new so why the recent interest in synthetic biology ?
I am too young to know if this has always been like this but I am inclined to think that this is just to product of increasing competition for resources (grant applications). Every once in a while scientist have to re-invent the pressing reasons why society has to invest in them. The big projects that will galvanize the masses, the next genome project.
I personally like the engineering approach to biology. Much of the work that is done in the lab where I am doing my phd is engineering oriented. Synthetic biology (or whatever it was called in the past and will be called in the future) could deliver things like cheap energy (biological solar panels),cheaper chemicals (optimized systems of production), cheap food (GMOs or some even weirder tissue cultures), clean water, improved immune-systems, etc. A quick look at the two reviews that are in this week's issue of Nature will tell you that we are still far from all of this.
The review by David Sprinzak and Michael Elowitz tries to cover broadly what as been achieved in engineering biological systems in the last couple of years (references range from 2000 to 2005). Apart from the reference to a paper on the engineering a mevalonate pathway in Escherichia coli, most of the work so far done in the field is preliminary. People have been trying to assemble simple systems and end up learning new things along the way.
The second review is authored by Drew Endy and is basically synthetic biology evangelism :). Drew Endy has been one of the voices shouting louder in support of this field and in looking for standardization and open exchange of information and materials (some notes from the biomass). The only new thing he says in this review that I have not heard before from him is a short paragraph on evolution. We are used to engineering things that do not replicate (cars, computers, tv sets, etc) and the field will have to start thinking of the consequences of evolution of the systems it tinkers with. Are the systems sustainable ? Will they change within their useful life time ?
There is one accompanying research paper reporting on a chimeric light sensing protein that is de-phosphorylated in the presence of red light. The bacteria produce lacZ in the dark and the production is decreased with increasing amounts of red light. You can make funny pictures with these bacteria but has for the real scientific value of this discovery I can link to two comments in Slashdot. Maybe that is exaggerated. Making chimeric protein receptors that work can be tricky and it is very nice that something started by college students can end up in a Nature paper.
Last but not least there is a comic ! The fantastic: "Adventures in Synthetic Biology". Ok, here is where I draw the line :) Who is this for ? Since when do teens read Nature ? How would they have access to this ? I like comics, I do ... but this is clearly not properly targeted.
This week Nature has a special issue on <buzz>Synthetic Biology</buzz>. I have currently a kind of love/hate relationship with trends in biology. It is easy to track the trends (in the recent past: genomics, proteomics, bioinformatics, systems biology, nanotechnology, synthetic biology) and it is somehow fascinating to follow them and watch them propagate. It holds for me a similar fascination has seeing a meme propagate in the web. Someone will still write a thesis on how a kid was able to put up a webpage like this one and make truck load of money selling pixels just because he ignited the curiosity of people on a global scale.
There is always a reason behind each rising trend in biology, but they are clearly too short lived to deliver on their expectations, so what is the point ? Why do these waves of buzz exist in research ? The mentality of engineering in biology is not new so why the recent interest in synthetic biology ?
I am too young to know if this has always been like this but I am inclined to think that this is just to product of increasing competition for resources (grant applications). Every once in a while scientist have to re-invent the pressing reasons why society has to invest in them. The big projects that will galvanize the masses, the next genome project.
I personally like the engineering approach to biology. Much of the work that is done in the lab where I am doing my phd is engineering oriented. Synthetic biology (or whatever it was called in the past and will be called in the future) could deliver things like cheap energy (biological solar panels),cheaper chemicals (optimized systems of production), cheap food (GMOs or some even weirder tissue cultures), clean water, improved immune-systems, etc. A quick look at the two reviews that are in this week's issue of Nature will tell you that we are still far from all of this.
The review by David Sprinzak and Michael Elowitz tries to cover broadly what as been achieved in engineering biological systems in the last couple of years (references range from 2000 to 2005). Apart from the reference to a paper on the engineering a mevalonate pathway in Escherichia coli, most of the work so far done in the field is preliminary. People have been trying to assemble simple systems and end up learning new things along the way.
The second review is authored by Drew Endy and is basically synthetic biology evangelism :). Drew Endy has been one of the voices shouting louder in support of this field and in looking for standardization and open exchange of information and materials (some notes from the biomass). The only new thing he says in this review that I have not heard before from him is a short paragraph on evolution. We are used to engineering things that do not replicate (cars, computers, tv sets, etc) and the field will have to start thinking of the consequences of evolution of the systems it tinkers with. Are the systems sustainable ? Will they change within their useful life time ?
There is one accompanying research paper reporting on a chimeric light sensing protein that is de-phosphorylated in the presence of red light. The bacteria produce lacZ in the dark and the production is decreased with increasing amounts of red light. You can make funny pictures with these bacteria but has for the real scientific value of this discovery I can link to two comments in Slashdot. Maybe that is exaggerated. Making chimeric protein receptors that work can be tricky and it is very nice that something started by college students can end up in a Nature paper.
Last but not least there is a comic ! The fantastic: "Adventures in Synthetic Biology". Ok, here is where I draw the line :) Who is this for ? Since when do teens read Nature ? How would they have access to this ? I like comics, I do ... but this is clearly not properly targeted.
Monday, November 21, 2005
BIND database runs out of funding
I only noticed today that BIND as ran out of funding. They say so on the home page and there are links to several paper regarding the issue of sustainable database funding (has of 16 November 2005).
From the frontpage of BIND:
"Finally, I would like to reiterate my conviction that public databases are essential requirements for the future of life sciences research. The question arises will these be free or will they require a subscription. Should BIND/Blueprint be sustained as a public-funded open-access database and service provider? "
I am not sure actually what would be a good way out for BIND. They could try to charge institutional access like the Faculty1000 or ISI. The other possibility would be to try to secure support from a place like NCBI or EBI. The problem is that there are several other databases available that do the same thing (MINT,DIP,GRID, IntAct,etc) so why should we pay for this service ? Why don't the protein-interaction databases fuse for example? I now that they agreed to share the data in the same format, so maybe there is not enough space for so many different databases developing new tools. The question is probably more of the curation effort then. Who should pay for the curation effort ? The users of the databases? The major institutions ? The journals (they could at least force the authors to submit interaction data directly) ?
There is also a link to the blog of Christopher Hogue called BioImplement. He expresses his views of the problem.
I only noticed today that BIND as ran out of funding. They say so on the home page and there are links to several paper regarding the issue of sustainable database funding (has of 16 November 2005).
From the frontpage of BIND:
"Finally, I would like to reiterate my conviction that public databases are essential requirements for the future of life sciences research. The question arises will these be free or will they require a subscription. Should BIND/Blueprint be sustained as a public-funded open-access database and service provider? "
I am not sure actually what would be a good way out for BIND. They could try to charge institutional access like the Faculty1000 or ISI. The other possibility would be to try to secure support from a place like NCBI or EBI. The problem is that there are several other databases available that do the same thing (MINT,DIP,GRID, IntAct,etc) so why should we pay for this service ? Why don't the protein-interaction databases fuse for example? I now that they agreed to share the data in the same format, so maybe there is not enough space for so many different databases developing new tools. The question is probably more of the curation effort then. Who should pay for the curation effort ? The users of the databases? The major institutions ? The journals (they could at least force the authors to submit interaction data directly) ?
There is also a link to the blog of Christopher Hogue called BioImplement. He expresses his views of the problem.
Saturday, November 19, 2005
Google Base simple tricks
I was playing with Gbase, just browsing for content and I noticed that when you search for content that already has a lot of entries you can restrict the outcome of the search very much like you do in a structured database. For example when you look for jobs you notice that in top you have "Refine your search" and you can click for example "job type" and if you select for example "permanent" you get something like all jobs where job type is permanent. It is all above in the URL so it is very simple to mess around until you can guess what most of those things are doing up there.
From this:
http://base.google.com/base/search?q=jobs&a_r=1&nd=0&scoring=r&us=0&a_n194=job+type&a_y194=1&a_s194=0&a_o194=0&a_v194=permanent&a_v194=
You really just need:
http://base.google.com/base/search?a_n194=job+type&a_y194=1&a_o194=0&a_v194=permanent
to get the same effect. Basically this gets all entries with "job type" equal "permanent". The 194 is not even important as long as the number is equal in all of the variables.
So this also gives the same:
http://base.google.com/base/search?a_n1=job+type&a_y1=1&a_o1=0&a_v1=permanent
a_n[identifier]=NAME
a_v[identifier]=VALUE
a_y[identifier]= ? (I think it is a boolean of some sort)
a_o[identifier]= how to evaluate the value 0=equal 1=less than 2=greater than
You can add construction like this to get an AND construction but so far I did not find an equivalent to an OR construction. This is almost good enough to work with.
So all protein sequences from S.cerevisiae would be:
http://base.google.com/base/search?a_n1=sequence+type&a_y1=1&a_o1=0&a_v1=protein&a_n2=species&a_y2=1&a_o2=0&a_v2=s.cerevisiae
I was playing with Gbase, just browsing for content and I noticed that when you search for content that already has a lot of entries you can restrict the outcome of the search very much like you do in a structured database. For example when you look for jobs you notice that in top you have "Refine your search" and you can click for example "job type" and if you select for example "permanent" you get something like all jobs where job type is permanent. It is all above in the URL so it is very simple to mess around until you can guess what most of those things are doing up there.
From this:
http://base.google.com/base/search?q=jobs&a_r=1&nd=0&scoring=r&us=0&a_n194=job+type&a_y194=1&a_s194=0&a_o194=0&a_v194=permanent&a_v194=
You really just need:
http://base.google.com/base/search?a_n194=job+type&a_y194=1&a_o194=0&a_v194=permanent
to get the same effect. Basically this gets all entries with "job type" equal "permanent". The 194 is not even important as long as the number is equal in all of the variables.
So this also gives the same:
http://base.google.com/base/search?a_n1=job+type&a_y1=1&a_o1=0&a_v1=permanent
a_n[identifier]=NAME
a_v[identifier]=VALUE
a_y[identifier]= ? (I think it is a boolean of some sort)
a_o[identifier]= how to evaluate the value 0=equal 1=less than 2=greater than
You can add construction like this to get an AND construction but so far I did not find an equivalent to an OR construction. This is almost good enough to work with.
So all protein sequences from S.cerevisiae would be:
http://base.google.com/base/search?a_n1=sequence+type&a_y1=1&a_o1=0&a_v1=protein&a_n2=species&a_y2=1&a_o2=0&a_v2=s.cerevisiae
Thursday, November 17, 2005
Google Base and Bioinformatics II
The Google Base service is officially open in beta (as usual). Is is mostly disappointing because you can do nothing with it really (read previous post). You can load tons of data, very rapidly although they take a lot of time to process the bulk uploads. Maybe this will speed up in the future. The problem is once you have your structured data in Google Base you cannot do anything with it apart from searching and looking at it with the browser. I uploaded a couple of protein sequences just for fun. I called the item "biological sequence" and I gave it very simple attributes like sequence, id, and type. The upload failed because I did not have a title so I added title and just copied the id field. Not very exciting right.
I guess you can scrape the data off it automatically but that is not very nice. This for example gets the object ids for the biological sequences I uploaded:
With the object ids then you can do the same to get the sequences.
Anyway, everybody is half expecting that one day google will release an API to do this properly. So coming back to scientific research, is this useful for anything ? Even with a proper API this is just a database. It will make it easy for people to rapidly set up a database and maybe google can make a simple template webpage service do display the content of the structured database. It would be a nice add-on to blogger for example. You could get a tile to put in your blog with an easy way to display the content of your structured database.
For virtual online collaborative research (aka science 2.0 :)?) this is potentially useful because you get a free tool to set up a database for a given project. Apart from this I don't see potential applications but like the name says it is just the base for something.
The Google Base service is officially open in beta (as usual). Is is mostly disappointing because you can do nothing with it really (read previous post). You can load tons of data, very rapidly although they take a lot of time to process the bulk uploads. Maybe this will speed up in the future. The problem is once you have your structured data in Google Base you cannot do anything with it apart from searching and looking at it with the browser. I uploaded a couple of protein sequences just for fun. I called the item "biological sequence" and I gave it very simple attributes like sequence, id, and type. The upload failed because I did not have a title so I added title and just copied the id field. Not very exciting right.
I guess you can scrape the data off it automatically but that is not very nice. This for example gets the object ids for the biological sequences I uploaded:
use LWP::UserAgent;
use HTTP::Request;
my $url = "http://base.google.com/base/search?q=biological+sequence";
my $ua = new LWP::UserAgent();
my $req = HTTP::Request->new('GET',$url);
my $res = $ua->request($req);
open(DATA, ">google.base.temp") || die "outputfile didn't open $!";
print DATA $res->content;
close DATA;
open (IN,"<google.base.temp")|| die "Error in input $!";
grep(/oid=([0-9]+)\">(\S+)</ && ($data{$1}=$2) ,<IN>);
close IN;
foreach $id (keys %data) {print $id,"\n";}
With the object ids then you can do the same to get the sequences.
Anyway, everybody is half expecting that one day google will release an API to do this properly. So coming back to scientific research, is this useful for anything ? Even with a proper API this is just a database. It will make it easy for people to rapidly set up a database and maybe google can make a simple template webpage service do display the content of the structured database. It would be a nice add-on to blogger for example. You could get a tile to put in your blog with an easy way to display the content of your structured database.
For virtual online collaborative research (aka science 2.0 :)?) this is potentially useful because you get a free tool to set up a database for a given project. Apart from this I don't see potential applications but like the name says it is just the base for something.
Monday, November 14, 2005
The Human Puppet
One of the current trends in our changing internet is the phenomena of "collective intelligence" (web2.0 buzz) where the rise and ease of individual participation can result in amazing collective efforts. The usual example for collective intelligence is the success of Wikipedia but more examples are sure to follow.
This sets the grounds for a possibly strange scenario in a kind of sci fi "what if" game. What if a human being decided that he/she did not want to decide anymore ? (funny paradox :) - "I'll be a vessel for the collective intelligence of the web, I'll be the human puppet". Taken to the extreme this someone would walk around with a webcam and with easy tools to constantly interact with the web. The ultimate big brother but voluntary. The masses in the web would constantly discuss and decide the life of the puppet. This someone would benefit from the knowledge and experience of a huge group of people and could, in theory really stand on the shoulders of giants.
Of course this is an extreme scenario that might not come to pass, but sci fi is useful to think of the possible consequences of a trend. Lighter versions of this scenario probably occur already in the blogosphere when people talk online about their daily lives and receive council from anonymous people.
Would someone ever give up their individuality to be directed by a collective intelligence ? Would a group of people be attracted by the chance of directing someone's life ?
One of the current trends in our changing internet is the phenomena of "collective intelligence" (web2.0 buzz) where the rise and ease of individual participation can result in amazing collective efforts. The usual example for collective intelligence is the success of Wikipedia but more examples are sure to follow.
This sets the grounds for a possibly strange scenario in a kind of sci fi "what if" game. What if a human being decided that he/she did not want to decide anymore ? (funny paradox :) - "I'll be a vessel for the collective intelligence of the web, I'll be the human puppet". Taken to the extreme this someone would walk around with a webcam and with easy tools to constantly interact with the web. The ultimate big brother but voluntary. The masses in the web would constantly discuss and decide the life of the puppet. This someone would benefit from the knowledge and experience of a huge group of people and could, in theory really stand on the shoulders of giants.
Of course this is an extreme scenario that might not come to pass, but sci fi is useful to think of the possible consequences of a trend. Lighter versions of this scenario probably occur already in the blogosphere when people talk online about their daily lives and receive council from anonymous people.
Would someone ever give up their individuality to be directed by a collective intelligence ? Would a group of people be attracted by the chance of directing someone's life ?
Thursday, November 10, 2005
In the latest issue of Current Biology there is a short two-page interview (sub-only) with Ronald Plasterk, current director of the Hubrecht Laboratory in Utrecht.
He had some very funny things to say about systems biology :
"The fundamental misconception of systems biology advocates is that one could create a virtual cell, and use big computers to model life and make discoveries. None of these modellers ever predicted that small microRNAs would play a role. One makes discoveries by watching, working, checking. They want to be Darwin, but do not want to waste years on the Beagle. They want sex but no love, icing but no cake. Scientific pornography."
I had a great laugh with this one :), however I happen to be working in a lab that is making software to exactly this and I disagree with this analogy. Of course you cannot discover something with your model about biological mechanisms that we know nothing about, but for sure that modeling approaches can help guide experimental work. If you model fails to explain an observation you can use the model to guide your next experiment. You go on by perfecting your model based on the results and so on. These cycles are not much different from what biologist have been doing intuitively but I think that few people would disagree that formalizing this process with the help of computational tools is a good idea.
He had some very funny things to say about systems biology :
"The fundamental misconception of systems biology advocates is that one could create a virtual cell, and use big computers to model life and make discoveries. None of these modellers ever predicted that small microRNAs would play a role. One makes discoveries by watching, working, checking. They want to be Darwin, but do not want to waste years on the Beagle. They want sex but no love, icing but no cake. Scientific pornography."
I had a great laugh with this one :), however I happen to be working in a lab that is making software to exactly this and I disagree with this analogy. Of course you cannot discover something with your model about biological mechanisms that we know nothing about, but for sure that modeling approaches can help guide experimental work. If you model fails to explain an observation you can use the model to guide your next experiment. You go on by perfecting your model based on the results and so on. These cycles are not much different from what biologist have been doing intuitively but I think that few people would disagree that formalizing this process with the help of computational tools is a good idea.
Sunday, November 06, 2005
The internet strategies of scientific journals
After a post in Nodalpoint about Nature's podcast I was left thinking a bit about the different responses of the different well known science journals to the increase of internet usage and changes in the technologies available.
I took a quick look at the publishing houses behind nature (Nature Publishing Group), cell (Cell Press), science (AAAS), PLoS and the BMC journals. There are a lot more publishers but these are sufficient to make the point.
What is the first impact? Only a fraction of these have the portal attitude (mostly Nature and the BMC journals) with content in the first page and gateways of specialized content. The rest have almost no real content apart from linking to the respective journals.
What if we try to dig further ? Well they all have an RSS feed to the content. Funny enough almost all of them have a jobs listing (except PLoS). Almost all have a list of most accessed articles (except Science).
Only Science and Nature produce news content for the general public that are good to attract other people than researchers to their sites. The equivalent in BMC would be the content of The Scientist that they have on the site and in PLoS it would be the synopsis that come with all papers.
How many allow for comments ? Only the two most recent publishers (BMC and PLoS) but PLoS is a bit more formal about it, and Science allow for comments online.
Then it comes downs to some particular content and services. BMC has several possible interesting services like the Peoples Archive, images MD, Primers in Biology. Then there is Nature with Connotea, Nature podcast, Nature products and Nature events.
So what is the point ? In the tech world first it was all about portals and creating content to keep people coming back. Nowadays it seems to be more about free services and there are very few of these publishers following the trend. Good services build brand and attract viewers.
The simple conclusion is that only Nature and BMC are building their sites and playing with new services like a tech company would and although the impact at present time is minimal, when researchers start using more online services these sites will have a head start.
After a post in Nodalpoint about Nature's podcast I was left thinking a bit about the different responses of the different well known science journals to the increase of internet usage and changes in the technologies available.
I took a quick look at the publishing houses behind nature (Nature Publishing Group), cell (Cell Press), science (AAAS), PLoS and the BMC journals. There are a lot more publishers but these are sufficient to make the point.
What is the first impact? Only a fraction of these have the portal attitude (mostly Nature and the BMC journals) with content in the first page and gateways of specialized content. The rest have almost no real content apart from linking to the respective journals.
What if we try to dig further ? Well they all have an RSS feed to the content. Funny enough almost all of them have a jobs listing (except PLoS). Almost all have a list of most accessed articles (except Science).
Only Science and Nature produce news content for the general public that are good to attract other people than researchers to their sites. The equivalent in BMC would be the content of The Scientist that they have on the site and in PLoS it would be the synopsis that come with all papers.
How many allow for comments ? Only the two most recent publishers (BMC and PLoS) but PLoS is a bit more formal about it, and Science allow for comments online.
Then it comes downs to some particular content and services. BMC has several possible interesting services like the Peoples Archive, images MD, Primers in Biology. Then there is Nature with Connotea, Nature podcast, Nature products and Nature events.
So what is the point ? In the tech world first it was all about portals and creating content to keep people coming back. Nowadays it seems to be more about free services and there are very few of these publishers following the trend. Good services build brand and attract viewers.
The simple conclusion is that only Nature and BMC are building their sites and playing with new services like a tech company would and although the impact at present time is minimal, when researchers start using more online services these sites will have a head start.
Thursday, November 03, 2005
Recent reads - two useful applications of bioinformatics
Is bioinformatics actually producing any useful tools or discovering anything new ? I would like to think so :). Here is a table from The Scientist showing the top ten cited papers of the last 2 years, last 10 years and of all time. Blast and Clustal are among the two ten cited papers in the last 10 years and MFold is within the top ten cited papers of the last two years.
Keeping in the spirit of practical applications of computational biology here two recent papers I read.
One is about the computational design of ribozymes. The authors computationally designed different ribozymes that could perform different logical functions. For example they were able to design a AND rybozyme that would self cleave only in the presence of two different particular oligos. They experimentally validated the results in vitro. These ribozymes can be combined to make more complicated circuits and could ultimately be used inside the cells to interfere with the networks in a rational matter or maybe to act as sensors,etc. They don't discuss how applicable this results are for in-vivo studies since ion content, pH and a lot of other things cannot be controlled in the same way.
Another interesting paper is about predicting the specificity of protein-DNA binding using structural models. They did this by developing a model for the free energy of protein-DNA interactions. With the model developed they could calculate the binding energy for structures of proteins bound to DNA and to any such complex after changing the bases in the DNA sites in contact with the protein. This results in a position specific scoring matrix that informs us of what are the preferred nucleotides at each positions for a particular DNA binding protein domain.
The protein-DNA interaction module is incorporated into the ROSETTA package. The authors provide all experimental datasets used in the supplementary material that other people might use to compare with other methods. The lab that I am working in has a similar software package called Fold-X.
Assuming that the structural coverage of biological parts will continue the current growing trend these structure based methods will become even more useful since one can in principle apply them by modeling the domain of interest by homology.
Is bioinformatics actually producing any useful tools or discovering anything new ? I would like to think so :). Here is a table from The Scientist showing the top ten cited papers of the last 2 years, last 10 years and of all time. Blast and Clustal are among the two ten cited papers in the last 10 years and MFold is within the top ten cited papers of the last two years.

Keeping in the spirit of practical applications of computational biology here two recent papers I read.
One is about the computational design of ribozymes. The authors computationally designed different ribozymes that could perform different logical functions. For example they were able to design a AND rybozyme that would self cleave only in the presence of two different particular oligos. They experimentally validated the results in vitro. These ribozymes can be combined to make more complicated circuits and could ultimately be used inside the cells to interfere with the networks in a rational matter or maybe to act as sensors,etc. They don't discuss how applicable this results are for in-vivo studies since ion content, pH and a lot of other things cannot be controlled in the same way.
Another interesting paper is about predicting the specificity of protein-DNA binding using structural models. They did this by developing a model for the free energy of protein-DNA interactions. With the model developed they could calculate the binding energy for structures of proteins bound to DNA and to any such complex after changing the bases in the DNA sites in contact with the protein. This results in a position specific scoring matrix that informs us of what are the preferred nucleotides at each positions for a particular DNA binding protein domain.
The protein-DNA interaction module is incorporated into the ROSETTA package. The authors provide all experimental datasets used in the supplementary material that other people might use to compare with other methods. The lab that I am working in has a similar software package called Fold-X.
Assuming that the structural coverage of biological parts will continue the current growing trend these structure based methods will become even more useful since one can in principle apply them by modeling the domain of interest by homology.
Tuesday, November 01, 2005
Our collective mind
As I sit here quietly blogging my thoughts away you are there listening. One click away and I share this with the world. Millions of clicks sharing their feelings, showing what they are seeing, calling out for attention, collectivly understanding the world. Amazing conversations are being automatically tracked around the whole world and we can participate. People are thinking that one day we will see emergent properties in the web. Something like it becoming alive. What do you mean .. one day ? One click more and another neuron fires, another pulse in the live wires connecting us all. We are just awaking up.
As I sit here quietly blogging my thoughts away you are there listening. One click away and I share this with the world. Millions of clicks sharing their feelings, showing what they are seeing, calling out for attention, collectivly understanding the world. Amazing conversations are being automatically tracked around the whole world and we can participate. People are thinking that one day we will see emergent properties in the web. Something like it becoming alive. What do you mean .. one day ? One click more and another neuron fires, another pulse in the live wires connecting us all. We are just awaking up.
Wednesday, October 26, 2005
Google Base and Bioinformatics
Google is creating a new service called Google Base. It looks like a general database service. Currently I cannot yet login but from the discussions around in the blogs we will be able to define content types and populate the database with our own content. I don't know how much space will be allocated to each user but I guess that this will be at least the disk space of our gmail accounts (around 2.5G currently and growing).
Can the bioinformatics community take advantage of this ?
Well one of the most boring tasks that we usually have to perform is cross-referencing databases. This usually means downloading some flat-files and spending some time scripting up some stuff. Of course some of the main databases take up way more then the 2.5G but we could imagine that having all databases under the same hosting service would help us. Probably Google Base will have a nice standard API that would come in handy for accessing all sorts of different data.
The next step would be the ability to do some processing on the data right on their servers. Please Google set up some clusters with some standard software and queuing systems. We have clusters here at EMBL but Google would do a lot of researchers a favor by "selling" computer processing time for some ads :).
Google is creating a new service called Google Base. It looks like a general database service. Currently I cannot yet login but from the discussions around in the blogs we will be able to define content types and populate the database with our own content. I don't know how much space will be allocated to each user but I guess that this will be at least the disk space of our gmail accounts (around 2.5G currently and growing).
Can the bioinformatics community take advantage of this ?
Well one of the most boring tasks that we usually have to perform is cross-referencing databases. This usually means downloading some flat-files and spending some time scripting up some stuff. Of course some of the main databases take up way more then the 2.5G but we could imagine that having all databases under the same hosting service would help us. Probably Google Base will have a nice standard API that would come in handy for accessing all sorts of different data.
The next step would be the ability to do some processing on the data right on their servers. Please Google set up some clusters with some standard software and queuing systems. We have clusters here at EMBL but Google would do a lot of researchers a favor by "selling" computer processing time for some ads :).
Protein Modules Consortium & Synthetic Biology
I have become a member of the Protein Modules Consortium, along with all participants in the FEBS course on modular protein domains that I attended recently. The aim of the consortium is the "promotion of scientific knowledge concerning the structure and function of protein modules, as well as the dissemination of scientific knowledge acquired by various means of communication".
Modular protein domains are "parts" inside a protein that can be regarded as a module. In this sense one could try to understand the function of a protein by understanding how the modular parts behave in the context of the whole protein. Another useful interpretation is that one should be able to create a database of modules that we can understand and create proteins with a predetermined function by copying and pasting the parts in the right way. Here are two short reviews on the subject. What would be the most efficient way of creating a database of protein parts that can be combined ? They should all be cloned into the vectors in the same way and there should be already tested protocols to rapidly combine the parts together. One of the future goals of the consortium, that was discussed in the FEBS course, is exactly to promote a set of cloning standards that could be used to this effect.
One possible strategy would be to use the Gateway cloning system. This is an in-vitro cloning method that is used for example by Marc Vidal's lab in the orfeome project of C. elegans. It is a reliable system , specially for small protein domains, and it is very fast. Compared to traditional cloning strategies it could be a bit more expensive but not much more if you consider the cost of the restriction/ligase enzymes. Creating an "entry" vector can be done with a PCR reaction followed by a recombination reaction (~2h) (followed by the usual transformation and sequencing steps) and this entry vector could be then stored in the databank. The biggest disadvantage mentioned for this cloning strategy is the reported low efficiency in cloning big proteins, but this would not be a problem for protein domains since the average protein domain size is around 100 amino-acids.
For reference, here is a paper where the authors compare different recombination systems, and another where the authors show a proof of principle experiment on how to use Gateway recombination to assemble functional proteins from cloned parts.
I have become a member of the Protein Modules Consortium, along with all participants in the FEBS course on modular protein domains that I attended recently. The aim of the consortium is the "promotion of scientific knowledge concerning the structure and function of protein modules, as well as the dissemination of scientific knowledge acquired by various means of communication".
Modular protein domains are "parts" inside a protein that can be regarded as a module. In this sense one could try to understand the function of a protein by understanding how the modular parts behave in the context of the whole protein. Another useful interpretation is that one should be able to create a database of modules that we can understand and create proteins with a predetermined function by copying and pasting the parts in the right way. Here are two short reviews on the subject. What would be the most efficient way of creating a database of protein parts that can be combined ? They should all be cloned into the vectors in the same way and there should be already tested protocols to rapidly combine the parts together. One of the future goals of the consortium, that was discussed in the FEBS course, is exactly to promote a set of cloning standards that could be used to this effect.
One possible strategy would be to use the Gateway cloning system. This is an in-vitro cloning method that is used for example by Marc Vidal's lab in the orfeome project of C. elegans. It is a reliable system , specially for small protein domains, and it is very fast. Compared to traditional cloning strategies it could be a bit more expensive but not much more if you consider the cost of the restriction/ligase enzymes. Creating an "entry" vector can be done with a PCR reaction followed by a recombination reaction (~2h) (followed by the usual transformation and sequencing steps) and this entry vector could be then stored in the databank. The biggest disadvantage mentioned for this cloning strategy is the reported low efficiency in cloning big proteins, but this would not be a problem for protein domains since the average protein domain size is around 100 amino-acids.
For reference, here is a paper where the authors compare different recombination systems, and another where the authors show a proof of principle experiment on how to use Gateway recombination to assemble functional proteins from cloned parts.
Monday, October 17, 2005
Your identity "aura"
I was thinking today of some possible future trends on our way to man-machine integration (known to some as the singularity :). More exactly I was thinking of all the recent moves on the portable devices, like the speed at which Apple is sending new iPods to the market and the Palm-Microsoft deal. The idea is simple and probably not very new. Wouldn't it be nice to carry your identity around in a machine readable format. It does not really matter in what way, it could be for example a device with wireless connection with a certain radius that you could turn on and off whenever you wished (any recent palm/cell-phone thing will have it nowadays). Now imagine you walk into a bar and the bar recognizes your identity, takes you list of music preferences from your music player or from the net and includes them into the statistical DJ playing stuff. This way the music the bar will play will be a balanced mesh of the tastes of the majority of people inside. The same way you could pass by any social place and check out the most used tags of the people inside to decide if this is the type of place for you. People broadcasting their identities would bring the same type of web 2.0 mesh/innovations to the social places around us in the real world.
I was thinking today of some possible future trends on our way to man-machine integration (known to some as the singularity :). More exactly I was thinking of all the recent moves on the portable devices, like the speed at which Apple is sending new iPods to the market and the Palm-Microsoft deal. The idea is simple and probably not very new. Wouldn't it be nice to carry your identity around in a machine readable format. It does not really matter in what way, it could be for example a device with wireless connection with a certain radius that you could turn on and off whenever you wished (any recent palm/cell-phone thing will have it nowadays). Now imagine you walk into a bar and the bar recognizes your identity, takes you list of music preferences from your music player or from the net and includes them into the statistical DJ playing stuff. This way the music the bar will play will be a balanced mesh of the tastes of the majority of people inside. The same way you could pass by any social place and check out the most used tags of the people inside to decide if this is the type of place for you. People broadcasting their identities would bring the same type of web 2.0 mesh/innovations to the social places around us in the real world.
Wednesday, October 12, 2005
In support of text mining
There is a commentary in Nature Biotech where the authors used text mining to look at how knowledge about molecular interactions grows over time. To do this, they used time-stamped statements about molecular interactions taken from full-text articles from 60 journals from 1999-2002. They describe how knowledge mostly expands from known "old" interactions instead of "jumping" to areas of the interaction space that is totally unconnected from previous knowledge. Since this work is based on statements about interactions I guess that the authors did not take into account the data coming from the high-throughput methods that is not described in the papers but is deposited in databases. In fact, in a recent effort to map the human protein-protein interaction network there was very little overlap between the know interactions and the new set of proposed interactions. What we might conclude from this is that although high-throughput methods are more error-prone than small-scale experiments they help us to jump to unexplored knowledge space.
The other two main conclusions of the commentary are that some facts are restricted to "knowledge pockets" and that only a small part of the network is growing at a given time. In general they try to make a case for the use of text mining but they do not go into the details of how this should be implemented. They do not talk about the possible roles of databases, tagging, journals, funding agencies, etc in this process of knowledge growth. Databases should help to solve the problem of knowledge pockets the authors mention. Tagging can eliminate the need for mining the data and journals/funding agencies have the power to force the authors to deposit the data in databases or tag their research along with the paper.
Without wanting to attract the wrath of people working on text mining, my opinion is that at least an equal amount of effort should be dedicated in making the knowledge that is discovered in the future easier to recollect.
There is a commentary in Nature Biotech where the authors used text mining to look at how knowledge about molecular interactions grows over time. To do this, they used time-stamped statements about molecular interactions taken from full-text articles from 60 journals from 1999-2002. They describe how knowledge mostly expands from known "old" interactions instead of "jumping" to areas of the interaction space that is totally unconnected from previous knowledge. Since this work is based on statements about interactions I guess that the authors did not take into account the data coming from the high-throughput methods that is not described in the papers but is deposited in databases. In fact, in a recent effort to map the human protein-protein interaction network there was very little overlap between the know interactions and the new set of proposed interactions. What we might conclude from this is that although high-throughput methods are more error-prone than small-scale experiments they help us to jump to unexplored knowledge space.
The other two main conclusions of the commentary are that some facts are restricted to "knowledge pockets" and that only a small part of the network is growing at a given time. In general they try to make a case for the use of text mining but they do not go into the details of how this should be implemented. They do not talk about the possible roles of databases, tagging, journals, funding agencies, etc in this process of knowledge growth. Databases should help to solve the problem of knowledge pockets the authors mention. Tagging can eliminate the need for mining the data and journals/funding agencies have the power to force the authors to deposit the data in databases or tag their research along with the paper.
Without wanting to attract the wrath of people working on text mining, my opinion is that at least an equal amount of effort should be dedicated in making the knowledge that is discovered in the future easier to recollect.
Saturday, October 08, 2005
Biology Direct
I am just propagating the announcement of a new journal. You can also read it in Propeller Twist and in Notes from the Biomass. There are tons of new journals coming up, so what is so interesting about this one ? Well they claim that they will implement a novel system of peer review where the author must find three board members to peer review the article. The paper is rejected if the author cannot get the board members to referee the work. Another interesting idea is that the referee can write comments to be published along with the paper. They plan to cover broadly the field of biology but they say that they will start off with Genomics, Bioinformatics and Systems Biology. The editorial board is full of very well know people from these areas so I assume that this is actually a journal to keep a look out for in the future.
I am just propagating the announcement of a new journal. You can also read it in Propeller Twist and in Notes from the Biomass. There are tons of new journals coming up, so what is so interesting about this one ? Well they claim that they will implement a novel system of peer review where the author must find three board members to peer review the article. The paper is rejected if the author cannot get the board members to referee the work. Another interesting idea is that the referee can write comments to be published along with the paper. They plan to cover broadly the field of biology but they say that they will start off with Genomics, Bioinformatics and Systems Biology. The editorial board is full of very well know people from these areas so I assume that this is actually a journal to keep a look out for in the future.
Connotea and tags
I have finally started using Connotea from Nature Publishing Group. I'm not a big user of these types of "social" web services like del.icio.us or Flickr but I thought I would give this a try since I do a lot of reading and I would like a nice way of keeping scientific reading organized. Here is my Connotea library.
When I first started downloading pdf files of interesting papers (some years ago) I used to put them neatly into folders organized by subject. Then, when the google desktop search started indexing PDFs I started just putting everything in one folder and I search for it when I want it back. Both ways work ok but the second ends up being faster.
So why should I use a web based reference manager to keep track of the papers I am interested in ? For one, because it takes almost to time at all. This was one of the nicest things about it. Just highlight the papers' DOI with the mouse and click a bookmarklet. Put in a couple of tags to describe the paper and it's done.
One other advantage of using this is the possibility of sharing the load of finding interesting papers with other people in the site with guilt by association.
I would like to see two tools added to Connotea, one is label clusters, like you see in Flickr and the other would be a graph of related papers or authors, like you can see when you click a news in the CNET news site.
In general I think that the tag/label concept is presently one of the best user driven modes of organizing knowledge. It takes the individual very little time to help out and the outcome is a vast amount of organized information. It is also probably a standard by now and this means that a lot of tools will be built to take advantage of this. Right now the tagging efforts are behind walls but there is no reason not to fuse "tag space" among different domains. Instead of an RSS aggregator we could have tag readers across different services. There is already a nice "tag reader" for del.icio.us called direc.tor.
Another useful tool would be a program to automatically label a document according to my labeling practices (or to someone else's habits). The program could scan through all the stuff I had labeled in the past and learn how to label or at least suggest labels for this new document. It could therefore also label whatever is in my computer. It would be close to indexing but more personalized :).
Further reading on the subject? Start here.
I have finally started using Connotea from Nature Publishing Group. I'm not a big user of these types of "social" web services like del.icio.us or Flickr but I thought I would give this a try since I do a lot of reading and I would like a nice way of keeping scientific reading organized. Here is my Connotea library.
When I first started downloading pdf files of interesting papers (some years ago) I used to put them neatly into folders organized by subject. Then, when the google desktop search started indexing PDFs I started just putting everything in one folder and I search for it when I want it back. Both ways work ok but the second ends up being faster.
So why should I use a web based reference manager to keep track of the papers I am interested in ? For one, because it takes almost to time at all. This was one of the nicest things about it. Just highlight the papers' DOI with the mouse and click a bookmarklet. Put in a couple of tags to describe the paper and it's done.
One other advantage of using this is the possibility of sharing the load of finding interesting papers with other people in the site with guilt by association.
I would like to see two tools added to Connotea, one is label clusters, like you see in Flickr and the other would be a graph of related papers or authors, like you can see when you click a news in the CNET news site.
In general I think that the tag/label concept is presently one of the best user driven modes of organizing knowledge. It takes the individual very little time to help out and the outcome is a vast amount of organized information. It is also probably a standard by now and this means that a lot of tools will be built to take advantage of this. Right now the tagging efforts are behind walls but there is no reason not to fuse "tag space" among different domains. Instead of an RSS aggregator we could have tag readers across different services. There is already a nice "tag reader" for del.icio.us called direc.tor.
Another useful tool would be a program to automatically label a document according to my labeling practices (or to someone else's habits). The program could scan through all the stuff I had labeled in the past and learn how to label or at least suggest labels for this new document. It could therefore also label whatever is in my computer. It would be close to indexing but more personalized :).
Further reading on the subject? Start here.
Monday, October 03, 2005
Recent reads
I am doing some boring repetitive jobs that take some time to run (I am so glad to have a cluster to work with) and in the middle of the job runs I took some time to catch up to some paper reading. So here is some of the interesting stuff:
Number one goes to a provocative review/opinion from Fox Keller E. called "Revisiting 'scale-free' networks." There is a comment about it in Faculty 1000. The author talks about power law distributions in an historical perspective removing some of the exaggerated hype and maybe overly optimistic notion that the observations about scale free networks might contain some sort of "universal" truth about complex networks.
I talked before about the work of Rama Ranganathan when I went to a FEBS course on modular protein domains. I said that he had talked about PDZ domains but it was actually WW domains :). Anyway , what he talked about in the meeting was published in two papers in Nature. They are worth a look, specially as a good example of the combination of computational and experimental work. This work exemplifies what I consider a nice role for computational biology, to guide the experimental work. They suggest what are the necessary constraints for a protein fold and then they built them to test their folding and activity experimentally.
Small is beautiful ? I am interested in protein network evolution and this small report by Naama Barkai's group caught my eye. It is a very simple work, they show an example where a cis regulatory motif sequence was dropped during evolution in the Saccharomyces lineage in several genes. I usually like small interesting ideas demonstrated nicely but I dare to say that maybe this one is slightly to simple :).
There is also a paper that I disliked. The paper talks about "The binding properties ad evolution of homodimers in protein-protein interaction networks" but most the conclusions look obvious or misleading. They say for example that a protein that has self interactions has higher average number of neighbors than a random protein. The comparison is not fair because a protein that has self interactions, in their analysis, has two or more interactions (including the self interaction) and a random protein has one or more interactions. The fair comparison would be to compare homodimers with proteins in the network that have at least two interactions.
I am doing some boring repetitive jobs that take some time to run (I am so glad to have a cluster to work with) and in the middle of the job runs I took some time to catch up to some paper reading. So here is some of the interesting stuff:
Number one goes to a provocative review/opinion from Fox Keller E. called "Revisiting 'scale-free' networks." There is a comment about it in Faculty 1000. The author talks about power law distributions in an historical perspective removing some of the exaggerated hype and maybe overly optimistic notion that the observations about scale free networks might contain some sort of "universal" truth about complex networks.
I talked before about the work of Rama Ranganathan when I went to a FEBS course on modular protein domains. I said that he had talked about PDZ domains but it was actually WW domains :). Anyway , what he talked about in the meeting was published in two papers in Nature. They are worth a look, specially as a good example of the combination of computational and experimental work. This work exemplifies what I consider a nice role for computational biology, to guide the experimental work. They suggest what are the necessary constraints for a protein fold and then they built them to test their folding and activity experimentally.
Small is beautiful ? I am interested in protein network evolution and this small report by Naama Barkai's group caught my eye. It is a very simple work, they show an example where a cis regulatory motif sequence was dropped during evolution in the Saccharomyces lineage in several genes. I usually like small interesting ideas demonstrated nicely but I dare to say that maybe this one is slightly to simple :).
There is also a paper that I disliked. The paper talks about "The binding properties ad evolution of homodimers in protein-protein interaction networks" but most the conclusions look obvious or misleading. They say for example that a protein that has self interactions has higher average number of neighbors than a random protein. The comparison is not fair because a protein that has self interactions, in their analysis, has two or more interactions (including the self interaction) and a random protein has one or more interactions. The fair comparison would be to compare homodimers with proteins in the network that have at least two interactions.
Monday, September 19, 2005
FEBS Course on Modular Protein Domains (Update)
The course finished some days ago and I just want to note down some of the interesting lectures. Nodalpoint has a discussion on blogging abut conferences. Should we talk about unpublished results presented in meetings ? Because it was such a small meeting with such an informal environment I will only mention work that was apparently finished.
Several talks were about domain specificity. How to define interaction specificity in the cell and what is the importance of domain specificity. For example, Cesareni talked about their work on the SH3 domains of S cerevisiae and how they have been using SPOT synthesis to discover the specificity and cross talk of the different domains. Sachdev Sidhu presented a study on PDZ domains of C elegans characterized by phage display. The study will give us a very large dataset of domain binding profiles and a look at the evolution of PDZ domains in C. elegans.
All this "simple" domain specificity has to be put into context if it is going to give us some biological insight. This issue was brought up by Rune Linding and Gary Bader, among others. We should add all possible information that is available in the species of interest and carefully combine them.
Rama Ranganathan gave a talk on the evolutionary constrains of a protein fold. The talked was centered on the PDZ domain but the methodology and concepts apply to any fold. He showed how one can use statistical coupling analysis to discover the positions in fold that are evolutionary correlated. This positions give us additional insight on the function of the fold.
Wendell A. Lim gave a fascinating talk on modular logic of cell signaling systems (buzzword: synthetic biology). His lab is working on modular allosteric protein gates and signaling rewiring. Most of what he talked about his from a recent review.
The course finished some days ago and I just want to note down some of the interesting lectures. Nodalpoint has a discussion on blogging abut conferences. Should we talk about unpublished results presented in meetings ? Because it was such a small meeting with such an informal environment I will only mention work that was apparently finished.
Several talks were about domain specificity. How to define interaction specificity in the cell and what is the importance of domain specificity. For example, Cesareni talked about their work on the SH3 domains of S cerevisiae and how they have been using SPOT synthesis to discover the specificity and cross talk of the different domains. Sachdev Sidhu presented a study on PDZ domains of C elegans characterized by phage display. The study will give us a very large dataset of domain binding profiles and a look at the evolution of PDZ domains in C. elegans.
All this "simple" domain specificity has to be put into context if it is going to give us some biological insight. This issue was brought up by Rune Linding and Gary Bader, among others. We should add all possible information that is available in the species of interest and carefully combine them.
Rama Ranganathan gave a talk on the evolutionary constrains of a protein fold. The talked was centered on the PDZ domain but the methodology and concepts apply to any fold. He showed how one can use statistical coupling analysis to discover the positions in fold that are evolutionary correlated. This positions give us additional insight on the function of the fold.
Wendell A. Lim gave a fascinating talk on modular logic of cell signaling systems (buzzword: synthetic biology). His lab is working on modular allosteric protein gates and signaling rewiring. Most of what he talked about his from a recent review.
Sunday, September 11, 2005
FEBS course on Modular Protein Domains
I am attending a FEBS course in Seefeld Austria on Modular Protein Domains.
I would like to highlight so far the short talk of Rune Linding on synthetic biology. He is working in the lab of Tony Pawson trying to develop a pipeline of generation of functional proteins from combination of domains.
One possible important outcome of this meeting might be the definition of some common cloning strategies and sharing of wet lab databases of cloned "parts". This will allow for an "open source" type of synthetic biology where everyone will be able to take advantage and built on top of other people's work. This would speed up innovation in a field that so far has produced interesting results of yet little useful applications.
I am attending a FEBS course in Seefeld Austria on Modular Protein Domains.
I would like to highlight so far the short talk of Rune Linding on synthetic biology. He is working in the lab of Tony Pawson trying to develop a pipeline of generation of functional proteins from combination of domains.
One possible important outcome of this meeting might be the definition of some common cloning strategies and sharing of wet lab databases of cloned "parts". This will allow for an "open source" type of synthetic biology where everyone will be able to take advantage and built on top of other people's work. This would speed up innovation in a field that so far has produced interesting results of yet little useful applications.
Tuesday, September 06, 2005
Chimp genome hype
Last week Nature journal dedicated a lot of the issue to "celebrate" the release of a draft version of the chimp genome. Why all this hype ? The amount of attention a genome sequence receives nowadays inversely correlates with the divergence time from human. The only outliers are genome of species related to human diseases or human habits. We want desperately to understand what makes us "different" but I am not sure that solving the chimp genome will actually tell us much about this.
We can benefit from a sequenced genome in two general ways: 1) provide a guide to the experimental work done with a species and 2) use it for comparative genomics studies to help highlight general principles. Clearly the chimp genome will be of use for people working on chimp biology but I doubt that the chimp genome can tell us much about the human species, simply because we are not actually that different and the small differences will be hard to find. I say this because the molecular basis for the changes that make us "unique" are most likely regulatory changes and these are very hard to spot by comparative genomics alone, particularly if the genomes used are of species that diverged recently from the species of interest.
It comes also of little surprise that the most interesting points about the comparative human-chimp analysis, described more in detail in accompanying articles, relate to evolutionary events that occur at a fast rates and can easily be detected, big changes in chromosomal arrangements.
A lot of discoveries will still be made with comparative genomics but it seams we are reaching a point when another genome adds more statistical power but reveals little surprises. Maybe we could focus some of the efforts and resources to gather other high throughput data like protein interaction networks, transcription factor binding sites, expression data ...
The same way we gain so much with comparative genomics we might gain a lot with the ability to compare different protein interaction networks.
Some thoughts from Bioinformatics blog
Last week Nature journal dedicated a lot of the issue to "celebrate" the release of a draft version of the chimp genome. Why all this hype ? The amount of attention a genome sequence receives nowadays inversely correlates with the divergence time from human. The only outliers are genome of species related to human diseases or human habits. We want desperately to understand what makes us "different" but I am not sure that solving the chimp genome will actually tell us much about this.
We can benefit from a sequenced genome in two general ways: 1) provide a guide to the experimental work done with a species and 2) use it for comparative genomics studies to help highlight general principles. Clearly the chimp genome will be of use for people working on chimp biology but I doubt that the chimp genome can tell us much about the human species, simply because we are not actually that different and the small differences will be hard to find. I say this because the molecular basis for the changes that make us "unique" are most likely regulatory changes and these are very hard to spot by comparative genomics alone, particularly if the genomes used are of species that diverged recently from the species of interest.
It comes also of little surprise that the most interesting points about the comparative human-chimp analysis, described more in detail in accompanying articles, relate to evolutionary events that occur at a fast rates and can easily be detected, big changes in chromosomal arrangements.
A lot of discoveries will still be made with comparative genomics but it seams we are reaching a point when another genome adds more statistical power but reveals little surprises. Maybe we could focus some of the efforts and resources to gather other high throughput data like protein interaction networks, transcription factor binding sites, expression data ...
The same way we gain so much with comparative genomics we might gain a lot with the ability to compare different protein interaction networks.
Some thoughts from Bioinformatics blog
Tuesday, August 30, 2005
A reflection on scientific journal publication by Philip Bourne
Philip Bourne wrote a very interesting perspective in the last issue of PLoS Computational Biology. He starts by comparing the somewhat convergent evolution of journal publishing and database submissions: "The daily work of any high-throughput scientific journal or biological database consists of information input, information processing, and information output." He also mentions the obvious difficulties of retrieval of information from scientific publications when compared to database data and raises some possibilities on what can be done to improve this. One would be to attribute digital object identifiers (DOI) to the items of content within biological databases. This would allow to track different publications referring to the same items to more easily retrieve the information from a paper automatically. Barend Mons wrote recently a commentary about exactly the same subject in BMC bioinformatics so there might be some grounds for agreement between some journals.
Phil Bourne also proposes that data in a publication should be more "alive". This reminded me of a recent discussion we had on Nodalpoint over reproducible research. Lastly Bourne also suggests that more data should be attached as meta data to the paper. As an example he suggests that gene names can be automatically retrieved and reviewed by the author with minimal effort and integrated with the paper as meta data. This point seems to me quite similar to first one, it would serve in essence to make it easier to retrieve information from a scientific publication.
It is nice to see the discussions coming up, now just find a way to get some journals together to agree on some formats and implementations. Make them opt-out, authors should do them or have to pay extra costs to have the publishing houses do it. Start making the papers on the web more connected to the databases, and vice versa. I want to click a protein name and have a list of possible databases to visit :). Add some kind of "trackback" to the databases, every paper mentioning a protein sends a trackback ping to the protein database and it is automatically updated.
Philip Bourne wrote a very interesting perspective in the last issue of PLoS Computational Biology. He starts by comparing the somewhat convergent evolution of journal publishing and database submissions: "The daily work of any high-throughput scientific journal or biological database consists of information input, information processing, and information output." He also mentions the obvious difficulties of retrieval of information from scientific publications when compared to database data and raises some possibilities on what can be done to improve this. One would be to attribute digital object identifiers (DOI) to the items of content within biological databases. This would allow to track different publications referring to the same items to more easily retrieve the information from a paper automatically. Barend Mons wrote recently a commentary about exactly the same subject in BMC bioinformatics so there might be some grounds for agreement between some journals.
Phil Bourne also proposes that data in a publication should be more "alive". This reminded me of a recent discussion we had on Nodalpoint over reproducible research. Lastly Bourne also suggests that more data should be attached as meta data to the paper. As an example he suggests that gene names can be automatically retrieved and reviewed by the author with minimal effort and integrated with the paper as meta data. This point seems to me quite similar to first one, it would serve in essence to make it easier to retrieve information from a scientific publication.
It is nice to see the discussions coming up, now just find a way to get some journals together to agree on some formats and implementations. Make them opt-out, authors should do them or have to pay extra costs to have the publishing houses do it. Start making the papers on the web more connected to the databases, and vice versa. I want to click a protein name and have a list of possible databases to visit :). Add some kind of "trackback" to the databases, every paper mentioning a protein sends a trackback ping to the protein database and it is automatically updated.
Friday, August 26, 2005
Celebrating my first paper as a first author
The third issue of PLoS Computational Biology is out and in it is the first paper I publish as a first author. It took some time to get it published but I am grateful for the useful reviewer comments. The two main points about this work is that SH3 domains preferentially bind unstructured protein regions and that there is an "optimal" divergence time that one should consider when selecting species to use when looking for conservation of SH3 target sites. If you are interested in this last point I encourage you to read the excellent paper by Sean R. Eddy "A Model of the Statistical Power of Comparative Genome Sequence Analysis" in PLoS Biology.
The third issue of PLoS Computational Biology is out and in it is the first paper I publish as a first author. It took some time to get it published but I am grateful for the useful reviewer comments. The two main points about this work is that SH3 domains preferentially bind unstructured protein regions and that there is an "optimal" divergence time that one should consider when selecting species to use when looking for conservation of SH3 target sites. If you are interested in this last point I encourage you to read the excellent paper by Sean R. Eddy "A Model of the Statistical Power of Comparative Genome Sequence Analysis" in PLoS Biology.
The future of medicine
From the Personal Genome and Bioinformatics blog, here is a link to some predictions on the future of medicine by Leroy Hood.
I would resume his ideas to 1)you will have your own genome sequenced cheaply and 2)we will have nanotech tools in medicine.
These two things will make medicine more preventive and it will allow humans to live longer. You can say that the ideas where presented in an overly exaggerated way but both ideas have been going around for a long time and I personally see them as very probable. It would be useful to know your own genetic predispositions and I'm sure that engineered proteins and protein complexes will play a role in future treatments.
Another important point is that science should be visible to society. People like Leroy Hood and Craig Venter can sometimes come up with "funny" ways of promoting their investments/research but they also bring science closer to society.
From the Personal Genome and Bioinformatics blog, here is a link to some predictions on the future of medicine by Leroy Hood.
I would resume his ideas to 1)you will have your own genome sequenced cheaply and 2)we will have nanotech tools in medicine.
These two things will make medicine more preventive and it will allow humans to live longer. You can say that the ideas where presented in an overly exaggerated way but both ideas have been going around for a long time and I personally see them as very probable. It would be useful to know your own genetic predispositions and I'm sure that engineered proteins and protein complexes will play a role in future treatments.
Another important point is that science should be visible to society. People like Leroy Hood and Craig Venter can sometimes come up with "funny" ways of promoting their investments/research but they also bring science closer to society.
Tuesday, August 23, 2005
Google Talk
There is a big buzz going around the web that tomorrow Google is going to release a IM service called Google Talk. The interesting thing is actually seeing the news going around the internet and geeks trying to connect to the service before it is available to the public. The image that came to mind was of a fire or a virus spreading fast. When they tried to get email users to switch they offered 1G of space, what are they going to offer tomorrow to make users switch to their IM ?
Update: Some beta version available here
Update 2: So there is nothing very special about it. The client is very simple and clean. The only interesting thing about this is not the client is the intention of making IM networks independent of the clients what makes a lot more sense for the users but I don't see yahoo and MSN messengers easily changing to a system like this and without them this is going to be very difficult.
There is a big buzz going around the web that tomorrow Google is going to release a IM service called Google Talk. The interesting thing is actually seeing the news going around the internet and geeks trying to connect to the service before it is available to the public. The image that came to mind was of a fire or a virus spreading fast. When they tried to get email users to switch they offered 1G of space, what are they going to offer tomorrow to make users switch to their IM ?
Update: Some beta version available here
Update 2: So there is nothing very special about it. The client is very simple and clean. The only interesting thing about this is not the client is the intention of making IM networks independent of the clients what makes a lot more sense for the users but I don't see yahoo and MSN messengers easily changing to a system like this and without them this is going to be very difficult.
Thursday, August 18, 2005
The h index
From a Nature news I found this paper on the h index. J. E. Hirsch proposes that the scientific performance for a researcher could be measured by this index h that he defines as : "the number of papers with citation number higher or equal to h".
From the news: "n h-index of 50, for example, means someone has written 50 papers that have each had at least 50 citations."
Such a measure would take the journal out of the rating and stop the current "rich get richer" trend for the impact factor. This way the author will focus more on the audience of the journal.
From a Nature news I found this paper on the h index. J. E. Hirsch proposes that the scientific performance for a researcher could be measured by this index h that he defines as : "the number of papers with citation number higher or equal to h".
From the news: "n h-index of 50, for example, means someone has written 50 papers that have each had at least 50 citations."
Such a measure would take the journal out of the rating and stop the current "rich get richer" trend for the impact factor. This way the author will focus more on the audience of the journal.
Saturday, August 06, 2005
On patent applications
In the last issue of Nature Biotech there was a list of recent patent applications in systems biology. Most of them are general ideas that have been published several times with different methods. I wonder how can a patent like this be approved and enforced when there are so many research papers available on the subject.
An example:
"A tool providing interactive capabilities for user involvement in extracting and disambiguating biological information in text; useful in generating a biological diagram."
A simple search for text mining in Pubmed will point you to more than 100 papers for example.
The same holds true for most of the other applications you can find in the table.
In the last issue of Nature Biotech there was a list of recent patent applications in systems biology. Most of them are general ideas that have been published several times with different methods. I wonder how can a patent like this be approved and enforced when there are so many research papers available on the subject.
An example:
"A tool providing interactive capabilities for user involvement in extracting and disambiguating biological information in text; useful in generating a biological diagram."
A simple search for text mining in Pubmed will point you to more than 100 papers for example.
The same holds true for most of the other applications you can find in the table.
Monday, August 01, 2005
Here is the provisional abstract for the work of the first year of my PhD. To be published soon in PLoS Computational Biology.
Reproducible research with the publication of a "compendium"
From Faculty1000 (sub only) I found this paper, from the people of the bioconductor project on a new way to publish results as a document where code and words are woven together to create a "compedium". The document can them be browsed and the code changed in an interactive way. The authors give a concrete example using R packages and data from Golub et al. on cancer classification by expression data analysis.
I never used R so I'm still messing around trying to install everything to try this properly but at first glance it looks like an interesting concept. This way with the publication of results you would get immediately the methods, you could change parameters to check some hypothesis, etc. It would certainly help referees to check some ideas quickly. Something like this could also be used in-house as a personal e-lab book to keep track of code, data and ideas.
From Faculty1000 (sub only) I found this paper, from the people of the bioconductor project on a new way to publish results as a document where code and words are woven together to create a "compedium". The document can them be browsed and the code changed in an interactive way. The authors give a concrete example using R packages and data from Golub et al. on cancer classification by expression data analysis.
I never used R so I'm still messing around trying to install everything to try this properly but at first glance it looks like an interesting concept. This way with the publication of results you would get immediately the methods, you could change parameters to check some hypothesis, etc. It would certainly help referees to check some ideas quickly. Something like this could also be used in-house as a personal e-lab book to keep track of code, data and ideas.
Friday, June 24, 2005
The first issue of PLoS Computational Biology is out. The journal's editors want this to be one of the main forums for the people working in the field of computational biology but so far what I would say is that it is nice to have another open access journal where we can aspire to publish our work.
I would like to point out the interesting perspective by Sean R. Eddy. Among several other interesting points he argues for interdisciplinary people instead of interdisciplinary teams and how the recent "big science" mentality might actually hinder innovation.
I would like to point out the interesting perspective by Sean R. Eddy. Among several other interesting points he argues for interdisciplinary people instead of interdisciplinary teams and how the recent "big science" mentality might actually hinder innovation.
Friday, June 10, 2005
Tagging your research
Here is a commentary that will sound very familiar to most bioinformaticians, something that a lot of us have been talking about. It argues for tagging papers prior to publication to make the data available for automatic processing. It would not be so difficult to have the text read by a tagging program and have the author go trough a list of terms to quickly accept/change/reject them. The effort would be minimal to the individual author when compared to the required effort to curate databases with all the available and ever increasing published papers. Just imagine the nice tools that could be built with such information rich databases.
Here is a commentary that will sound very familiar to most bioinformaticians, something that a lot of us have been talking about. It argues for tagging papers prior to publication to make the data available for automatic processing. It would not be so difficult to have the text read by a tagging program and have the author go trough a list of terms to quickly accept/change/reject them. The effort would be minimal to the individual author when compared to the required effort to curate databases with all the available and ever increasing published papers. Just imagine the nice tools that could be built with such information rich databases.
Friday, May 27, 2005
MSN messenger search
Another step in Microsoft's attempt to get into the search market :). The brute force way ... anywhere they can put a search tool for MSN search they will.
Another step in Microsoft's attempt to get into the search market :). The brute force way ... anywhere they can put a search tool for MSN search they will.
Rise of the Plagiosphere
This is an interesting article about the increase in awareness on the whole human knowledge. The basic statement is that there is an increase in our capabilities of searching through what is already been written and therefore the act of plagiarizing will be more apparent. The author goes on to state that this might increase our sense of futility. Our ideas will be ours no longer because most likely it has been thought of before and it is one click away.
I would say that there is an optimist side to this. More search capabilities also means an increased ability to share our ideas in the global village. I think innovation is very much driven by the ability to share and build on top of preexisting ideas. Therefore an increase in search capabilities for me sounds a lot like a drive for innovation.
This is an interesting article about the increase in awareness on the whole human knowledge. The basic statement is that there is an increase in our capabilities of searching through what is already been written and therefore the act of plagiarizing will be more apparent. The author goes on to state that this might increase our sense of futility. Our ideas will be ours no longer because most likely it has been thought of before and it is one click away.
I would say that there is an optimist side to this. More search capabilities also means an increased ability to share our ideas in the global village. I think innovation is very much driven by the ability to share and build on top of preexisting ideas. Therefore an increase in search capabilities for me sounds a lot like a drive for innovation.
Friday, May 13, 2005
Monkeys Brains Alter to Work Robotic Arm
More work from Miguel Nicolelis' lab shows that the concept of self is very plastic. They show the brain adapts by plastically dedicating some "brain structure" for the control of the robot arm.
He talked about this in his seminar in one of my phd courses. It does resonate well with our intuitive feeling about tools. If we move to a different keyboard, and it has a different layout we will be severely slowed down. People that drive a car most likely will describe the experience of driving like the car is somewhat an extension of self. They will probably look at the mirrors without noticing they are doing so, etc.
In this sense, becoming an expert with any tool will mean that we are incorporating this tool into our concept of self. This came into my mind when I realized once that I was using google in the middle of a instant messeger chat with a friend to look for something he wrote down instead of asking him about it. Is web search becoming an extension of our brain ? :) One day we will unconsciously stop storing information in our wet brain because it is there at simple recall distance away in our internet brain.
More work from Miguel Nicolelis' lab shows that the concept of self is very plastic. They show the brain adapts by plastically dedicating some "brain structure" for the control of the robot arm.
He talked about this in his seminar in one of my phd courses. It does resonate well with our intuitive feeling about tools. If we move to a different keyboard, and it has a different layout we will be severely slowed down. People that drive a car most likely will describe the experience of driving like the car is somewhat an extension of self. They will probably look at the mirrors without noticing they are doing so, etc.
In this sense, becoming an expert with any tool will mean that we are incorporating this tool into our concept of self. This came into my mind when I realized once that I was using google in the middle of a instant messeger chat with a friend to look for something he wrote down instead of asking him about it. Is web search becoming an extension of our brain ? :) One day we will unconsciously stop storing information in our wet brain because it is there at simple recall distance away in our internet brain.
Modular machine assembles copies of itself in minutes.
Rather simple but elegant self assembly of robots. From the movie we can see a tower replicating by picking up pieces at predetermined places and putting them together to form a copy of itself.
It would look a lot cooler to have something like a "cube dispenser". All cubes should be able to communicate with each other. "dead" creatures should return themselves to the cube dispenser unit. "live" creatures all know were to get the cubes from and how to replicate themselves. Some mutations should be possible in order to make more complex creatures. Add some goals like the machine the moves more or the machine that can move some objects is allowed to replicate more.
With these simple type of rules and some more complex body parts they would start to have some very interesting robots.
Rather simple but elegant self assembly of robots. From the movie we can see a tower replicating by picking up pieces at predetermined places and putting them together to form a copy of itself.
It would look a lot cooler to have something like a "cube dispenser". All cubes should be able to communicate with each other. "dead" creatures should return themselves to the cube dispenser unit. "live" creatures all know were to get the cubes from and how to replicate themselves. Some mutations should be possible in order to make more complex creatures. Add some goals like the machine the moves more or the machine that can move some objects is allowed to replicate more.
With these simple type of rules and some more complex body parts they would start to have some very interesting robots.
Thursday, May 05, 2005
Lights on Seattle
The move into city wide wireless coverage continues. This example is a very expensive, business only example, but I'm sure more will follow. In a couple of years we will have the broad band connectivity anywhere. I still feel that the man-machine interfaces are not progressing with the same speed but maybe with the connectivity availability more pressure to build new interfaces will come up.
The move into city wide wireless coverage continues. This example is a very expensive, business only example, but I'm sure more will follow. In a couple of years we will have the broad band connectivity anywhere. I still feel that the man-machine interfaces are not progressing with the same speed but maybe with the connectivity availability more pressure to build new interfaces will come up.
Sunday, April 24, 2005
Anyone interested in synthetic biology ? :)
taqdot: News for the open source and synthetic biology community
taqdot: News for the open source and synthetic biology community
Saturday, March 26, 2005
Grafedia: "grafedia: words written anywhere, then linked to images, video or sound files online"
Here is a nice concept. A physical hyperlink. You can "click" the real world to discover a hidden context. Sounds cool :)
Here is a nice concept. A physical hyperlink. You can "click" the real world to discover a hidden context. Sounds cool :)
Friday, December 03, 2004
GEO World News - Geo.tv: "UN members rebuff US criticism, support Annan"
Just wanted to voice my support as well :) This guy is a very good diplomat and here are the US trying to get him out of the UN.
Just wanted to voice my support as well :) This guy is a very good diplomat and here are the US trying to get him out of the UN.
Thursday, December 02, 2004
news@nature.com�-�Iris Murdoch's last book reveals early Alzheimer's: "A vocabulary analysis of the final book by British novelist Iris Murdoch reveals the early stages of the Alzheimer's disease that killed her, neuroscientists have found. The discovery shows that even before she was diagnosed with the disease, her work betrayed the subtle signs of her condition."
I do not know why but this feels a bit sad. A brain on the decline is always a difficult image to picture. I'm also not sure if the technique will be always useful. It would probable be enough if the writer decides to write something different for "usual" and the computational method would flag it as decline maybe.
I do not know why but this feels a bit sad. A brain on the decline is always a difficult image to picture. I'm also not sure if the technique will be always useful. It would probable be enough if the writer decides to write something different for "usual" and the computational method would flag it as decline maybe.
Tuesday, November 09, 2004
Forbes.com: Race-Based Medicine, Genomics, and You: "Race-Based Medicine, Genomics, and You "
This is the first time I'm aware of a "race" specific drug. The drug works better in the African-Americans than in whites. There is no idea yet if the difference is due to genetic differences but this a clear possibility.
Whatever the reason for this difference in the effect for this particular drug I think this type of possibly genotype specific drugs is going to increase a lot in the near future. The goals of cheap genome sequencing and personalized medicine will see to that.
This is the first time I'm aware of a "race" specific drug. The drug works better in the African-Americans than in whites. There is no idea yet if the difference is due to genetic differences but this a clear possibility.
Whatever the reason for this difference in the effect for this particular drug I think this type of possibly genotype specific drugs is going to increase a lot in the near future. The goals of cheap genome sequencing and personalized medicine will see to that.
Thursday, October 21, 2004
Google's desktop liberation tool - ZDNet UK Comment
There are a lot of different comments on Google's release of the desktop tool. These are, I think, the most thrilled comments I have read :)
There are a lot of different comments on Google's release of the desktop tool. These are, I think, the most thrilled comments I have read :)
Wednesday, October 06, 2004
Wired 12.10: The Long Tail: "Forget squeezing millions from a few megahits at the top of the charts. The future of entertainment is in the millions of niche markets at the shallow end of the bitstream."
There is hope for the future of entertainment. We might be able to overcome the current hits-only market.
There is hope for the future of entertainment. We might be able to overcome the current hits-only market.
Tuesday, October 05, 2004
Google Wins �X� prize by Launching Into Space (Life on Other Planets)
"The acquisition of Joe Beda, who did a lot of work on the Avalon user interface for Longhorn, seems to open the door for the concept of a browser with a Gass-like 3D view of the web"
A google web browser ? That would be interesting. Microsoft has said that they would attack the web search market, Google lunched Gmail on beta and now might be thinking about a browser... Counter attack ?
"The acquisition of Joe Beda, who did a lot of work on the Avalon user interface for Longhorn, seems to open the door for the concept of a browser with a Gass-like 3D view of the web"
A google web browser ? That would be interesting. Microsoft has said that they would attack the web search market, Google lunched Gmail on beta and now might be thinking about a browser... Counter attack ?
Reuters Health Information (2004-10-04): U.S. scientists win Nobel prize for smell research: ".S. scientists win Nobel prize for smell research"
Not the most exciting of discoveries ...
Not the most exciting of discoveries ...
Monday, October 04, 2004
Wired News: Genome Model Applied to Software
"What does uncovering the secret language of DNA have in common with reverse-engineering Microsoft software? "
This is the first time I see bioinformatics tools helping people working with information technology problems. After years of one way traffic in knowledge sharing it might be that bioinformatics is producing useful general tools :) great stuff
"What does uncovering the secret language of DNA have in common with reverse-engineering Microsoft software? "
This is the first time I see bioinformatics tools helping people working with information technology problems. After years of one way traffic in knowledge sharing it might be that bioinformatics is producing useful general tools :) great stuff
Tuesday, September 28, 2004
Reuters | Latest Financial News / Full News Coverage: "Thailand said on Tuesday it had found its first known probable case of a human being infecting another with bird flu, but insisted it was an isolated incident that posed little risk to the greater population."
This sounds very dangerous. Let's be optimistic and think that maybe it is really an isolated event.
This sounds very dangerous. Let's be optimistic and think that maybe it is really an isolated event.
Tuesday, August 10, 2004
Michael Nielsen: Principles of Effective Research: "Principles of Effective Research
By Michael A. Nielsen"
A very nice essay on how to live a research career. Talks about the importance of balancing research activities with personal life; balancing self-development and the creative process; maintaining self-discipline.
By Michael A. Nielsen"
A very nice essay on how to live a research career. Talks about the importance of balancing research activities with personal life; balancing self-development and the creative process; maintaining self-discipline.
Saturday, August 07, 2004
Wired 12.08: Craig Venter's Epic Voyage to Redefine the Origin of the Species
He trying to "sequence Mother Earth". Traveling the world collecting samples of bacterial ecosystems , and sequencing their genomes. He will just probably get a parts list of new genes but he then wants to put them in a minimal genome and figure out what they do.
Imagine what we will be able to do with the huge parts list he is creating.
He trying to "sequence Mother Earth". Traveling the world collecting samples of bacterial ecosystems , and sequencing their genomes. He will just probably get a parts list of new genes but he then wants to put them in a minimal genome and figure out what they do.
Imagine what we will be able to do with the huge parts list he is creating.
Friday, August 06, 2004
Trojan Horse Charges PDAs:
"It's a natural trend. Where technology goes, viruses will follow,' he said. 'The perception is that as new technology moves into the mobile market, these threats will move in that direction also."
"It's a natural trend. Where technology goes, viruses will follow,' he said. 'The perception is that as new technology moves into the mobile market, these threats will move in that direction also."
Wednesday, July 21, 2004
Citrina Summary
"Citrina (pronounced sih-TREE-nuh) is a database management tool that automates the mirroring and processing of databases that are distributed via ftp servers. It is built around the Ant java build tool making it very flexible and portable. Citrina only provides the basic functionality for mirroring but can easily be extended to do other tasks. For example, with Citrina you could mirror the uniprot database to your local system, generate fasta files, create the blast dbs, and run blast on a set of proteins you are interested in."
Have to keep this in mind for possible automization protocols
"Citrina (pronounced sih-TREE-nuh) is a database management tool that automates the mirroring and processing of databases that are distributed via ftp servers. It is built around the Ant java build tool making it very flexible and portable. Citrina only provides the basic functionality for mirroring but can easily be extended to do other tasks. For example, with Citrina you could mirror the uniprot database to your local system, generate fasta files, create the blast dbs, and run blast on a set of proteins you are interested in."
Have to keep this in mind for possible automization protocols
Saturday, July 17, 2004
BioMed Central | Full text | Mistaken Identifiers: Gene name errors can be introduced inadvertently when using Excel in bioinformatics
Too funny to be true :). It is a serious problem but I am amazed on how this "bug" got reported as an scientific paper.
Too funny to be true :). It is a serious problem but I am amazed on how this "bug" got reported as an scientific paper.
Thursday, July 15, 2004
MacDevCenter.com: Bioinformatics and Comparative Genomics
A wonderful analogy to comparative genomics :)
"Geographic maps are a useful analogy for how we study genomes. If you were given a detailed map of London, you could learn a lot about what defines a large cosmopolitan city. You would see a large number of apartments, shops, and restaurants and might reasonably conclude that these are essential for life in the city. But you could not assess the relative importance of unique features like Buckingham Palace or the Brick Lane street market.
Things would be clearer if you were also given a detailed map of Paris. That too has apartments, shops, and restaurants, confirming your earlier hypothesis. It also has street markets, so perhaps those are an important, albeit secondary, aspect of city life. In contrast, Paris has no "active" royal palaces. Why not? One interpretation might be that Buckingham Palace is an important feature that distinguishes London from other cities. Another might be that a royal family has no function whatsoever in a modern society and survives in London merely as an evolutionary remnant. "
A wonderful analogy to comparative genomics :)
"Geographic maps are a useful analogy for how we study genomes. If you were given a detailed map of London, you could learn a lot about what defines a large cosmopolitan city. You would see a large number of apartments, shops, and restaurants and might reasonably conclude that these are essential for life in the city. But you could not assess the relative importance of unique features like Buckingham Palace or the Brick Lane street market.
Things would be clearer if you were also given a detailed map of Paris. That too has apartments, shops, and restaurants, confirming your earlier hypothesis. It also has street markets, so perhaps those are an important, albeit secondary, aspect of city life. In contrast, Paris has no "active" royal palaces. Why not? One interpretation might be that Buckingham Palace is an important feature that distinguishes London from other cities. Another might be that a royal family has no function whatsoever in a modern society and survives in London merely as an evolutionary remnant. "
Friday, July 09, 2004
MIT Biological Engineering Division: "Writing DNA: First Synthetic Biology Conference Held at MIT"
The outcome of the Synthetic Biology Conference seams to be the beginnings of a community dedicated on thinking biology in a technology frame of mind.
This would be very useful:
"Endy said that he and his colleagues want to "put in place the technical infrastructure to make routine the design and fabrication of many-component, integrated biological systems."
The outcome of the Synthetic Biology Conference seams to be the beginnings of a community dedicated on thinking biology in a technology frame of mind.
This would be very useful:
"Endy said that he and his colleagues want to "put in place the technical infrastructure to make routine the design and fabrication of many-component, integrated biological systems."
Tuesday, June 22, 2004
Economist.com | REPORTS: "Medicine: The open-source model is a good way to produce software, as the example of Linux shows. Could the same collaborative approach now revitalise medical research too?"
Thursday, June 17, 2004
Quantum physics: Push-button teleportation: "Quantum physics: Push-button teleportation "
Two groups reported the generation of coherent superpositions of two internal states for a single trapped ion, and have teleported these quantum states to a second ion. It is not quite "beam me up" but it seams to be of possible interest for quantum computation.
Two groups reported the generation of coherent superpositions of two internal states for a single trapped ion, and have teleported these quantum states to a second ion. It is not quite "beam me up" but it seams to be of possible interest for quantum computation.
Wednesday, June 16, 2004
IOL: Computers / IT
"The first-ever computer virus that can infect cellphones has been discovered, anti-virus software developers said on Tuesday, adding that up until now it has had no harmful effect."
Here we go ... it did not take them that long to come up with a cell phone virus. This is going to be a big long term problem. We are getting increasingly dependent on connectivity and the virus "spps." and number keeps on growing at a incredible rate. Soon they will make a virus that replicates and changes itself by code mutations and somebody will have to invent some sort of immune system that adjust automatically :D.
"The first-ever computer virus that can infect cellphones has been discovered, anti-virus software developers said on Tuesday, adding that up until now it has had no harmful effect."
Here we go ... it did not take them that long to come up with a cell phone virus. This is going to be a big long term problem. We are getting increasingly dependent on connectivity and the virus "spps." and number keeps on growing at a incredible rate. Soon they will make a virus that replicates and changes itself by code mutations and somebody will have to invent some sort of immune system that adjust automatically :D.
Monday, June 14, 2004
Las Vegas SUN: German Researcher Stripped of Doctoral: "Schoen, now 34, was fired by Bell Laboratories in New Jersey in September 2002 after an outside review committee concluded that he made up or altered data 16 times while working in the hot fields of superconductivity and molecular electronics.
Findings he helped research were published in prominent journals such as Science, Nature and Applied Physics Letters. "
They are removing is doctorate credentials. It should be really hard to go from possible Nobel winner to losing everything ... but if he did fake all the work, he deserves it.
Findings he helped research were published in prominent journals such as Science, Nature and Applied Physics Letters. "
They are removing is doctorate credentials. It should be really hard to go from possible Nobel winner to losing everything ... but if he did fake all the work, he deserves it.
Friday, June 11, 2004
Directory of open access
journals
A service created to cover free, full text journals. The project is funded by Open Society Institute - Budapest and also supported by SPARC (The Scholarly Publishing and Academic Resources Coalition).
http://www.osi.hu/infoprogram/
http://www.arl.org/sparc/
Journals that has an embargo period will not be added.
This is a pity. They should also include papers released after the embargo period.
journals
A service created to cover free, full text journals. The project is funded by Open Society Institute - Budapest and also supported by SPARC (The Scholarly Publishing and Academic Resources Coalition).
http://www.osi.hu/infoprogram/
http://www.arl.org/sparc/
Journals that has an embargo period will not be added.
This is a pity. They should also include papers released after the embargo period.
Thursday, June 03, 2004
Gene regulation: A reason for reading nonsense
The process of transcribing DNA can itself regulate gene expression in yeast: in the case concerned it is the very act of reading the DNA, not the message produced, that carries out the regulatory job.
----------------------------------------------------------
A simple example where the RNA polymerase disrupts the expression of a gene by production of a upstream non-coding sequence. The message is not important only the actual reading trough the downstream promoter.
The process of transcribing DNA can itself regulate gene expression in yeast: in the case concerned it is the very act of reading the DNA, not the message produced, that carries out the regulatory job.
----------------------------------------------------------
A simple example where the RNA polymerase disrupts the expression of a gene by production of a upstream non-coding sequence. The message is not important only the actual reading trough the downstream promoter.
Double check casts doubt on statistics in published papers
A study highlighting statistical gaffes in scientific literature has brought renewed calls for vigilance among mathematically challenged researchers and journal editors.
------------------------------------------------
Maths in Biology .. still not up to it.
A study highlighting statistical gaffes in scientific literature has brought renewed calls for vigilance among mathematically challenged researchers and journal editors.
------------------------------------------------
Maths in Biology .. still not up to it.
Sunday, May 09, 2004
Synthetic Biology: "The First International Meeting on Synthetic Biology"
The MIT ppl are marking territory :). The buzzword seems to be catching up fast. I think at least in the next couple of years it is a safe bet to go for Synthetic Biology
The MIT ppl are marking territory :). The buzzword seems to be catching up fast. I think at least in the next couple of years it is a safe bet to go for Synthetic Biology
Subscribe to:
Posts (Atom)